Why Traditional Reputation Management Fails in the AI Era
AI systems decide what to recommend based on signals most companies can't control.
When a potential customer asks an AI assistant for the best vendor in a category, it names two or three brands with complete confidence, and it ignores a dozen others that spent years building search rankings and review scores. That single exchange is the clearest evidence that something fundamentally different is happening in how businesses get evaluated now, and the old playbook for managing a company's standing has no lever to pull on it.
How AI systems form opinions about businesses
A search engine crawls pages, indexes them, and ranks them against a query, so a business that wants to be found can study the ranking factors and build toward them with reasonable confidence about cause and effect. An AI system does something else entirely: it synthesizes an answer from patterns absorbed across enormous volumes of training data, and in systems like Perplexity that pull live web content at the moment of a query, it blends that synthesis with real-time retrieval, drawing on an accumulated impression built from everything it has read about that brand across the web, weighted by how often and how consistently that impression appears across sources the model treats as credible.
Once a model links a brand to a set of attributes, accurate or not, that link tends to reappear across different kinds of queries, so the pattern works something like institutional memory. A company that repositioned its product line two years ago may still get described in terms of its old positioning, simply because the newer signals haven't yet built up enough weight in the training or retrieval data to override the older pattern. Search doesn't carry this kind of lag in the same way. A page re-indexes, a ranking shifts, and you see the update within days. An AI system's impression of a brand can take much longer to catch up to reality, and sometimes never does.
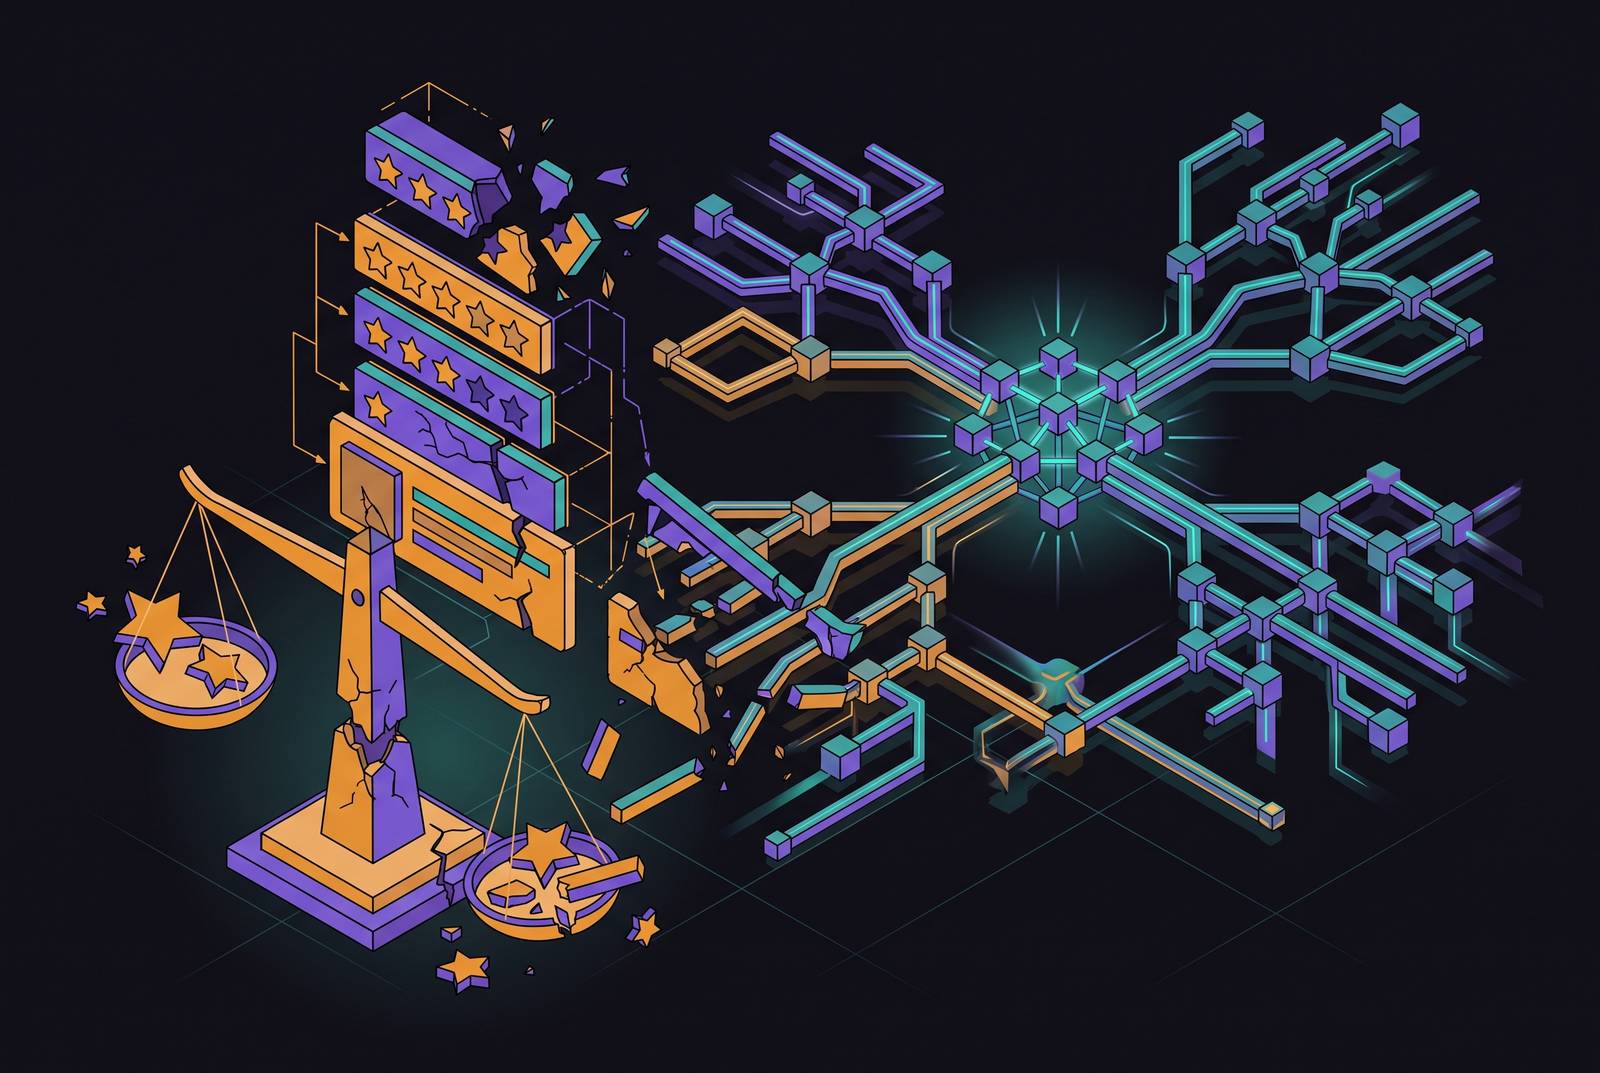
This is why ranking and representation have become two separate problems, since a business can hold the top organic position on a major search engine for its most competitive keyword and still find itself absent from an AI-generated answer to a closely related question, or described there in terms it wouldn't recognize. Meanwhile, a company with middling SEO metrics but strong topical authority, built through sustained coverage in publications the model treats as trustworthy, can show up well-represented in AI outputs, even if it never optimized a single landing page for search. The old toolkit, built around star ratings on review platforms, SERP rank tracking, share of voice in press coverage, keyword placement, and backlink accumulation, was built for a world where a human reads a list of options and clicks one. None of those metrics were designed to describe how a model decides what to say in a single synthesized answer, and the standard web analytics dashboard built to track them has no column for it.
Why the signals that shape AI perception sit mostly outside the brand's direct control
The research on how these models form brand associations points to one consistent finding: a company's own website is a minor input into what an AI system eventually says about it. The signals that carry real weight are earned media coverage, mentions in publications the model treats as authoritative, review platforms, community discussion, and the recurring way a brand gets characterized across the open web, most of which a company doesn't write and can't directly edit. This is the structural core of the mismatch. The old approach assumed a company could shape its own standing by controlling its owned channels and nudging a handful of measurable external levers, like backlinks and review counts. AI perception runs on a different map of influence almost entirely outside that control.
Domain authority illustrates the shift concretely. That metric correlates weakly with which sources get selected into AI Overviews, while what the research calls E-E-A-T signals, meaning experience, expertise, authoritativeness, and trust as expressed through independent, third-party-verified content, carry far more weight. A business can't self-declare its own trustworthiness into an AI system's output. That trust has to be conferred by other sources the model already treats as credible, which puts the lever for an awful lot of brand perception in the hands of journalists, reviewers, and independent commentators a company may never interact with directly.
Platform fragmentation adds a second dimension to the same problem. Different AI systems draw on different source pools and apply different internal criteria for what counts as authoritative, so a brand can be well-represented in one system's answers but carry a damaging or outdated characterization in another's. A company that only tracks its standing on one platform is working from a partial map while believing it has the whole territory. And the stakes of this fragmented picture are rising as AI agents start acting on these characterizations directly. When an AI agent recommends a vendor and proceeds to act on that recommendation with no human stopping to browse, compare, or double-check in between, a misrepresentation becomes a lost transaction that nobody at the company ever had the chance to intercept.
How AI systems decide which brands to mention, cite, and recommend
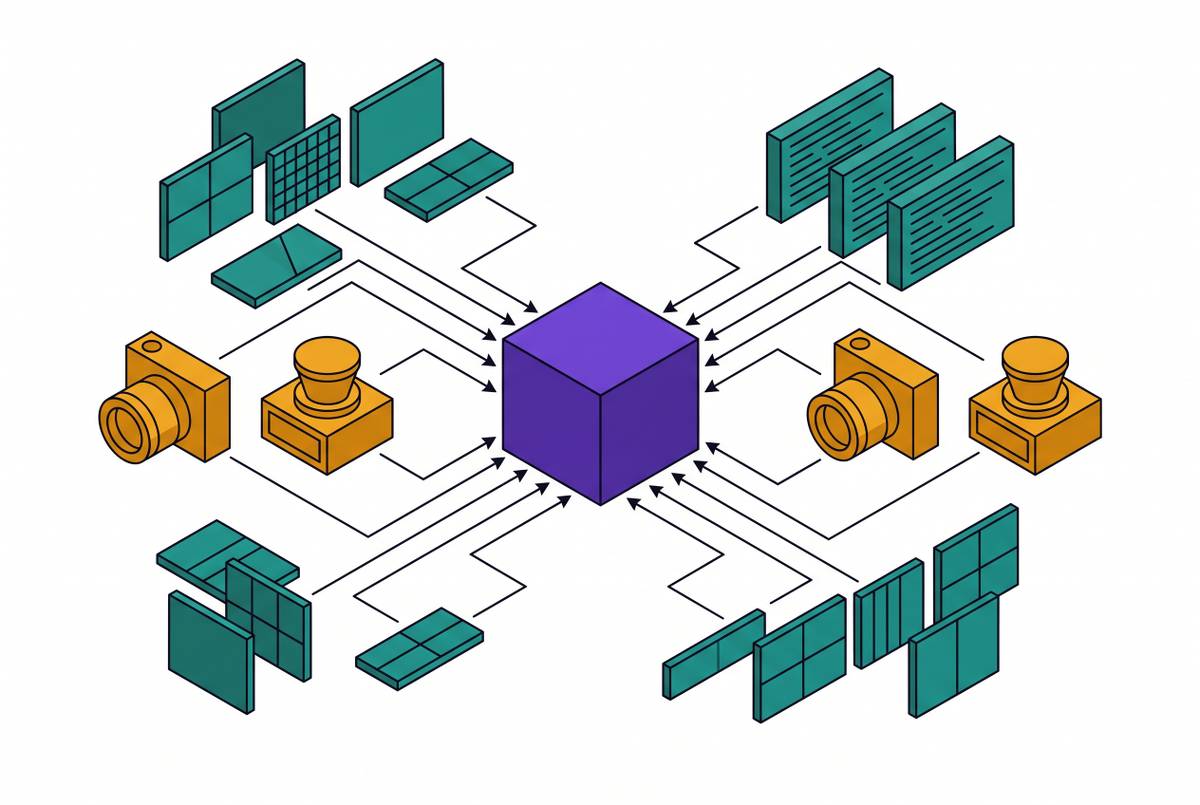
A credibility logic that can be described with some precision underlies the apparent unpredictability of AI-generated answers. Three mechanisms do most of the work: co-occurrence patterns, entity recognition, and the E-E-A-T signals embedded in third-party content. These are measurable patterns in how training and retrieval data get weighted, and understanding them is the precondition for doing anything useful about them.
Co-occurrence is the most basic of the three. When a brand shows up repeatedly alongside the terms that define its category, the problems it solves, and other sources the model already trusts, the model learns to associate that brand with that category. A brand that's absent from those contexts doesn't get ranked lower in the way a page might rank lower in search results. It's simply missing from the model's learned narrative of the category altogether, which is a harder problem to notice and a harder one to fix.
Entity recognition works as a kind of precondition for all of this. A brand needs a consistent, verifiable presence that AI systems can resolve to a single identity before any of the other signals can accumulate properly. Without that foundation, a business risks being omitted, confused with a similarly named competitor, or described inconsistently depending on which system is answering and which sources it happened to draw from for that particular query.
Volatility is a built-in feature of the system, not a glitch to be fixed. A large share of brands don't maintain stable visibility from one AI answer to the next, even when the underlying query stays the same, which makes a single snapshot audit close to useless as a measure of real standing. Only repeated measurement across many prompts, platforms, and time periods produces a reliable picture of where a brand actually stands.
The last dimension, accuracy of attributes, tends to be the one businesses discover latest and find hardest to stomach. A model might describe a company's positioning, its target customer, or its capabilities based on outdated content, stale third-party write-ups, or framing that happens to favor a competitor, and the business has no real-time way of catching this without actively watching for it.
Taken together, these four dimensions explain why the metrics traditional methods produce, star ratings, SERP rank, domain authority, share of voice in press, don't function as stand-ins for AI standing. They describe a different evaluator's judgment, and treating them as a proxy for how AI systems perceive a brand produces wrong conclusions about as often as it produces right ones. A new measurement vocabulary has emerged to fill the gap. Share of Model, the percentage of AI-generated responses across a defined set of queries that mention a given brand, functions as the headline visibility metric for this era, and it has no analogue in a traditional ORM dashboard; no SERP position or review count can be used to back into it. Around that core metric sits a fuller set of measures: brand mention share, topical visibility, prompt-level visibility, domain influence and citation share, sentiment distribution across different query types, and AI-driven traffic and conversion. Cross-platform consistency rounds out the picture as its own measurable dimension, since a brand that performs well on one AI system and poorly on another has no way to detect that gap through conventional monitoring. The underlying phenomenon, often called cross-model perception drift, is real and measurable: the same brand, asked about through the same underlying question, can come back characterized in materially different terms depending on which system answered. Platforms built for this kind of multi-signal, multi-evaluator scoring, Evident among them, have emerged so they can track these dimensions together instead of treating any single one as a complete picture.
The compounding difficulty: AI perception optimization can conflict with human trust
Even grasping these mechanics fully still leaves a business facing a harder problem: optimizing a brand's signals for how AI systems perceive it, without regard to how actual human readers respond, can quietly erode the trust that makes a recommendation worth having. The academic literature on Generative Engine Optimization makes this discomfort precise: heuristics that work in one context transfer poorly to another, competitive dynamics between brands chasing the same citations can erode everyone's individual gains, and content rewritten specifically to earn citations can end up performing worse in retrieval than content written for a human reader. The shorthand that circulates in a lot of early AI-optimization advice, publish more third-party content and earn more citations, understates how easily that same effort can backfire.
The deeper tension is that human audiences and AI systems don't always reward the same signals. Content engineered heavily toward citation and retrieval patterns can read as inauthentic or promotional to a human being encountering it directly, and a brand that over-indexes on satisfying an algorithm's preferences risks damaging the very credibility that earns it genuine third-party mentions. The signals that build AI visibility are largely earned through human-authored third-party content, so a strategy that alienates human readers eventually starves the AI-facing signal too.
None of this argues for giving up on AI-facing strategy. It argues for a different architecture. Businesses need to treat algorithms, AI systems, and human audiences as three distinct evaluators, and each one has its own partially overlapping but non-identical set of signal requirements. Optimizing hard for one at the expense of the other two is a structural error, because none of the three evaluators can be fully satisfied by signals built for only one of them.
What practitioners can do with the signals AI reads
The fix has to happen upstream, in the content, entities, and third-party sources that AI systems actually ingest, rather than downstream in the outputs those systems produce. A misleading or outdated AI answer is a symptom; the cause lives in the underlying signal environment that produced it, and that's the only place a correction can actually take hold.
If an AI system misrepresents a brand, whether through outright hallucination or reliance on outdated source material, you have to fix it through the sources feeding that system, not through the output itself. That means identifying what's actually driving the error, correcting it at the source wherever that's possible, and publishing well-sourced content elsewhere to counterbalance it where a direct correction isn't available.
Entity recognition has to come first as a foundation, not as an afterthought. A business needs a consistent, verified presence across the authoritative directories and reference sources that AI systems use to resolve identity. Without that groundwork, a brand's mentions stay inconsistent or go missing across different platforms, no matter how good the content behind them is.
Earned third-party presence has to be pursued on purpose, as its own strategic objective rather than a hoped-for byproduct of other marketing work. The signals most reliably tied to AI visibility are mentions in earned media, expert reviews, and community discussion, not the volume of pages a company publishes on its own site. Content strategy has to shift its center of gravity from producing more owned pages toward earning more third-party mentions in places that are already trusted.
Owned-channel ambiguity needs to be cleaned up as its own task. Small inconsistencies in how a brand describes itself, its positioning, or basic facts across its own profiles compound into confused or contradictory AI characterizations faster than most teams expect. A human reader can reconcile a few conflicting details without much effort, but an AI system tends to compress that same conflict into one simplified story, and it isn't guaranteed to pick the accurate version.
Monitoring has to run continuously and across multiple platforms, not as a single audit at a point in time. Visibility in AI responses fluctuates enough that one measurement tells a business almost nothing reliable about where it actually stands; the only way to know is repeated measurement across multiple AI systems, multiple query types, and multiple points in time, the kind of multi-signal tracking that measurement platforms in this space, Evident included, were built to provide.
Measurement itself has to come first, not last. The businesses that manage this well will be the ones that establish a baseline score across all three evaluator types, algorithmic, AI, and human, before deciding which signals to prioritize or which fixes to chase. Optimizing before measuring is optimizing blind, and in a landscape this fragmented, blind optimization accomplishes almost nothing.