Platforms That Score Brand Perception Across AI Rankers and Human Audiences Simultaneously
Brands need separate scores for AI visibility, AI sentiment, and human perception to compete.
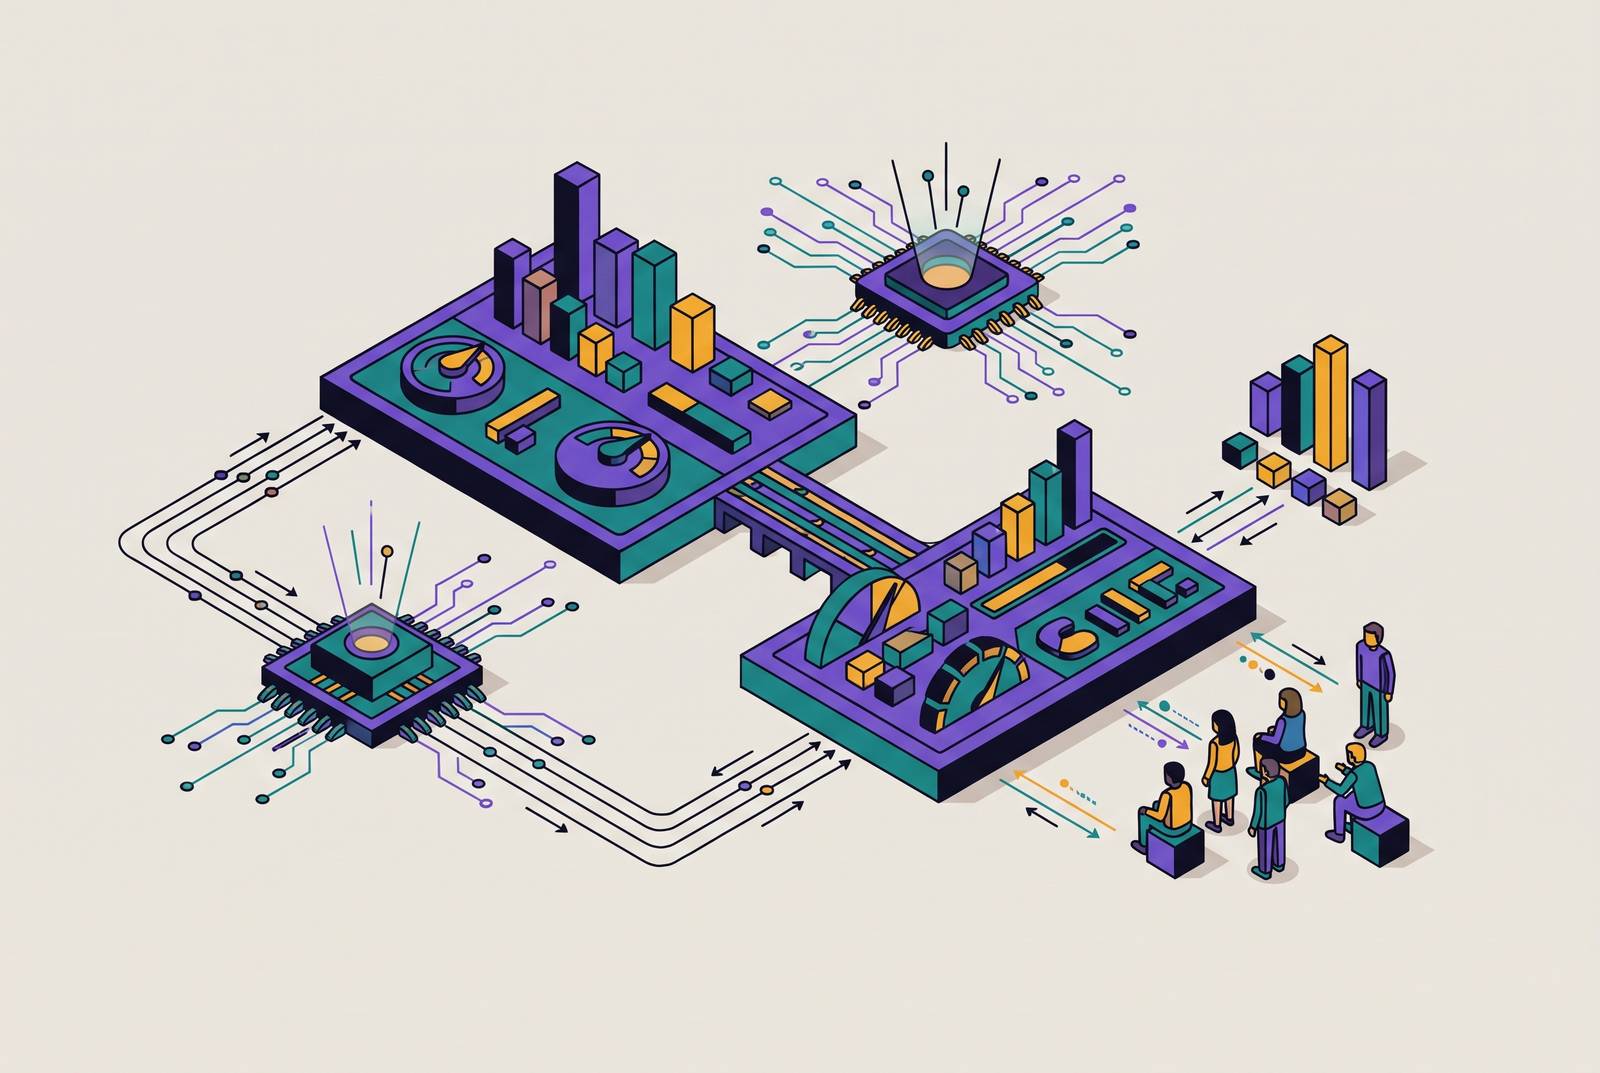
A perception intelligence platform for AI era brands must measure search visibility, AI representation, and human sentiment separately. Platforms that score brand perception across AI rankers and human audiences at the same time need their own signals and methods for each dimension. The practical test is whether they expose the gaps between those scores and connect them to prioritized actions.
Why brand perception now has three separate scorecards
A brand can rank first in traditional search, be absent from AI-generated answers, and be regarded warmly by its customers. None of those results contradicts the others. Traditional search algorithms use authority, relevance, and technical signals to compare pages and give each a place on a list. Large language models synthesize answers that typically name only a handful of brands. Their decisive mechanism is inclusion, because a brand either enters the answer or remains outside it.
Direct experience, peer opinion, reviews, and media shape judgments that are affective and social. A favorable customer view therefore cannot establish whether an AI assistant recommends the brand, just as a search position cannot establish customer trust. Each score answers a different question about the same business. A single-channel score is structurally inadequate when it is used to stand for all three.
What AI systems actually measure when they evaluate a brand
AI brand assessment draws on two stages, namely what is encoded in training data and what live retrieval supplies. A model can surface a brand without retrieving a web page when that brand appears frequently in high-quality training material. This is brand memory built from semantic density. The distinction changes what the measurement must capture. Search position alone does not reveal how firmly a model associates a brand with a category or use case.
Retrieval adds another source of evidence to that representation. Presence on G2, Capterra, and Trustpilot correlates with meaningfully higher citation rates because these trusted, frequently crawled, multi-brand sources provide validated evidence. Entity clarity influences whether that evidence resolves into one coherent brand. Organization schema and sameAs attributes help connect a brand’s disparate web presence into an entity graph. Without those connections, ambiguity reduces citation confidence, so AI evaluation is not simply traditional SEO with a different output format.
Why AI sentiment and AI visibility are two different problems
GrowByData Compass tracked Azazie at a Favorability Score of 73.7 in ChatGPT and 96.7 in Google AI Mode across the same prompts from August 24 to September 22, 2026. The gap was 23 points between engines. In the same dataset, Petal & Pup’s overall score of 97.5 masked a notably weaker position in Google AI Overviews. Each engine constructs its answer from its own sources, producing a different framing of the same brand.
Visibility records whether the brand appears, while sentiment captures the tone and framing of that appearance. Frequent mentions can still position a brand narrowly as “the budget option,” which may not match its intended use case. Neutral wording is not inherently unfavorable, since a factual description can sit inside a recommendation. The underlying statement distinguishes useful neutrality from a misleading association. This measurement captures what a buyer reads in an AI answer before visiting the brand’s site.
How AI perception drifts over time even when nothing visible changes
LLM perception drift is the month-over-month change in how models reference and position brands within a category. In a tracked case of project management software, Atlassian’s score rose by more than five points between September and October 2025 while Slack fell by more than eight points. There was no visible market event that explained the change. With products unchanged, the shifts reflected changes in how models weighted ecosystem breadth and contextual density. This makes a point-in-time audit an incomplete account of AI perception.
Drift is measurable, which makes it manageable. Brands with strong cross-product ecosystems that appear across many conceptual neighborhoods have AI positioning that is steadier and more favorable. AI brand signal stability measures that consistency across retraining cycles, while volatility signals fragile semantic anchoring. Stability is therefore a distinct KPI from share of voice or keyword rankings. Faruk Tugtekin’s AI Perception Index also found that a brand with $29M in funding and a bootstrapped brand scored nearly identically. That finding separates AI perception from funding level and supports the conclusion that favorable positioning is earnable.
What human-audience perception measurement contributes that AI tracking cannot
AI output describes a model’s representation of a brand. It does not establish whether customers recognize that description in their own experience. Listen Labs’ method shows this gap by comparing LLM descriptions with data from consumer interviews. An LLM may describe a brand as “trusted” while consumers hesitate at the word “reliable.” The contradiction becomes a measurable perception gap.
Human research also gathers evidence that AI outputs cannot hold. Tone of voice, subconscious micro-expressions, and emotional hesitation provide affective signals that predict outcomes such as purchase and advocacy. Those signals answer a different question from whether a model includes a brand in its response. Combining the two methods allows the comparison to address both representation and experience. Without that human evidence, a favorable AI description could be taken as proof that customers trust the brand.
The methodological requirement is therefore more demanding than adding social mentions to an AI dashboard. Human evidence must be structured enough to compare with AI-side findings, while remaining a separate measure of customer experience. A qualitative reading can reveal a contradiction, but it cannot by itself support comparison with a visibility score at scale. Both data streams are needed to locate the gap.
What platforms help brands understand how AI systems perceive them versus how humans do?
GrowByData Compass measures AI sentiment for each engine and does not use consumer research to find out how people see a brand. As of October 2026, it tracks ChatGPT, Google AI Mode, and Google AI Overviews. It reports a Favorability Score, positive, neutral, and negative sentiment composition, and the underlying statements by engine, location, and prompt group. Its scope makes cross-engine differences visible without hiding them inside a blended result. That is an AI-side measurement capability, not a substitute for human-audience data.
BERA.ai launched LLM Brand Rankings in June 2026 to connect rankings from Gemini, ChatGPT, and Claude with BERA Score and Love Curve position comparisons. Its business impact analysis shows how AI visibility and brand equity are linked to sales, revenue, and enterprise value. Evident scores all three dimensions using more than 400 signals that cover how algorithms, AI, and humans judge a brand. Its scoring is designed to provide an actionable view of those dimensions and surface what to address first.
Siftly operates in what its own assessment calls the “optimization-integrated” tier. It combines multi-engine tracking with prescriptive content guidance, including entity clarity and FAQ schema recommendations. Guidance is bundled into the platform rather than left to a separate consulting step. Its stated scope connects AI findings to content changes. Across these platforms, the concrete comparison is between engine-level diagnosis, links to brand equity, three-dimension scoring, and integrated optimization guidance.
The capability gap between monitoring tools and scoring platforms
Basic mention tracking counts references to a brand. Without sentiment analysis, citation attribution, or competitive context, it cannot show whether those references help or hurt how people see the brand. Deep analytics also tracks more than one engine and measures share of voice, competitive benchmarking, and sentiment composition. Optimization-integrated platforms then use those findings to recommend actions, such as improving entity clarity or adding FAQ schema to a page. Human-audience integration also links AI-side scores to what consumers feel about the brand.
Coverage is independent of that depth of analysis. Siftly’s platform analysis says that tracking fewer than four major LLMs leaves systematic blind spots because engines favor different types of content. Perplexity favors earned media, while Google AI Overviews surfaces a more balanced mix. Even a close look at one engine cannot explain gaps in how different engines portray a brand. The number of tracked mentions does not resolve that limitation.
This spectrum is useful only in relation to the buyer’s needs. A smaller brand may need only the analytics tier, while an enterprise brand that manages how it is seen across many markets needs the full stack. More capability is not automatically a better fit. The relevant distinction is whether the platform supplies the evidence and action guidance required for the decisions at hand.
The signals that drive AI perception scores and how they differ from SEO signals
Earned media and third-party coverage have disproportionate weight in AI citation logic. Brands are 6.5 times more likely to be cited in AI answers through third-party sources than through their own domains. Even high-quality content on a brand’s own site may therefore go uncited when other sites do not back it up. The location of the evidence is part of its value to a generative engine.
Entity clarity helps tie that outside evidence to the same brand. Organization schema supplies the name, URL, logo, contact details, and entity connections that help an AI system form a confident brand representation. Freshness supplies a different signal because AI crawlers target recently published content. Visible dates and JSON-LD dateModified provide human-readable and machine-readable recency information. These signals show which brand the evidence concerns and how up to date it is, going beyond conventional search authority.
E-E-A-T also plays a different role in how AI chooses what to cite. AI systems evaluate off-site validation, including authoritative publications that mention or link to the brand, trusted platforms that reference it, and broader web consensus about credibility. Traditional SEO still contributes to that picture. A page-one Google ranking for relevant queries provides an additional trust signal, but it does not guarantee AI inclusion. The relationship is asymmetric because AI inclusion increasingly supports discovery independently of search rank.
For teams evaluating improvement options, these differences explain why a change can benefit one scorecard without moving another. Entity clarity addresses ambiguity, freshness addresses recency, and third-party presence supplies external validation. A generic recommendation to improve SEO does not distinguish those functions. A useful scoring platform connects its findings to the relevant signal rather than treating every visibility gap as the same problem.
What a unified perception score requires that no single-channel tool can provide
Scoring all the dimensions at once requires measuring each in its own right. AI-side results need model-level separation, time-series tracking, and connections to the signals behind the score. Human data needs to be organized well enough to show where generated descriptions differ from what customers experience. Algorithmic measurement contributes the technical and authority signals that determine search visibility and underpin the wider evidence set. A unified view integrates these dimensions without making them interchangeable.
The resulting discipline is perception intelligence rather than an expanded name for SEO, social listening, or traditional brand tracking. An AI representation can be favorable but inaccurate, a customer view can be positive but absent from generated answers, and search authority can coexist with weak AI inclusion. Those conditions call for different responses. Measurement must precede optimization because the size and source of each gap determine which response deserves priority.
For a brand evaluating platforms, the lesson is to test whether AI and human scores remain separate, whether drift is tracked over time, and whether findings connect to prioritized actions. Algorithmic credibility must also be measured separately from AI visibility. Feature lists cannot establish that methodological coverage. The choice ultimately turns on which dimensions a platform can actually score and whether those scores support a defensible decision about what to address first.