What a Multi-Signal Presence Score Actually Measures Across Search, AI, and Social
Tracking presence across search, AI, and social reveals where your brand is invisible to buyers.
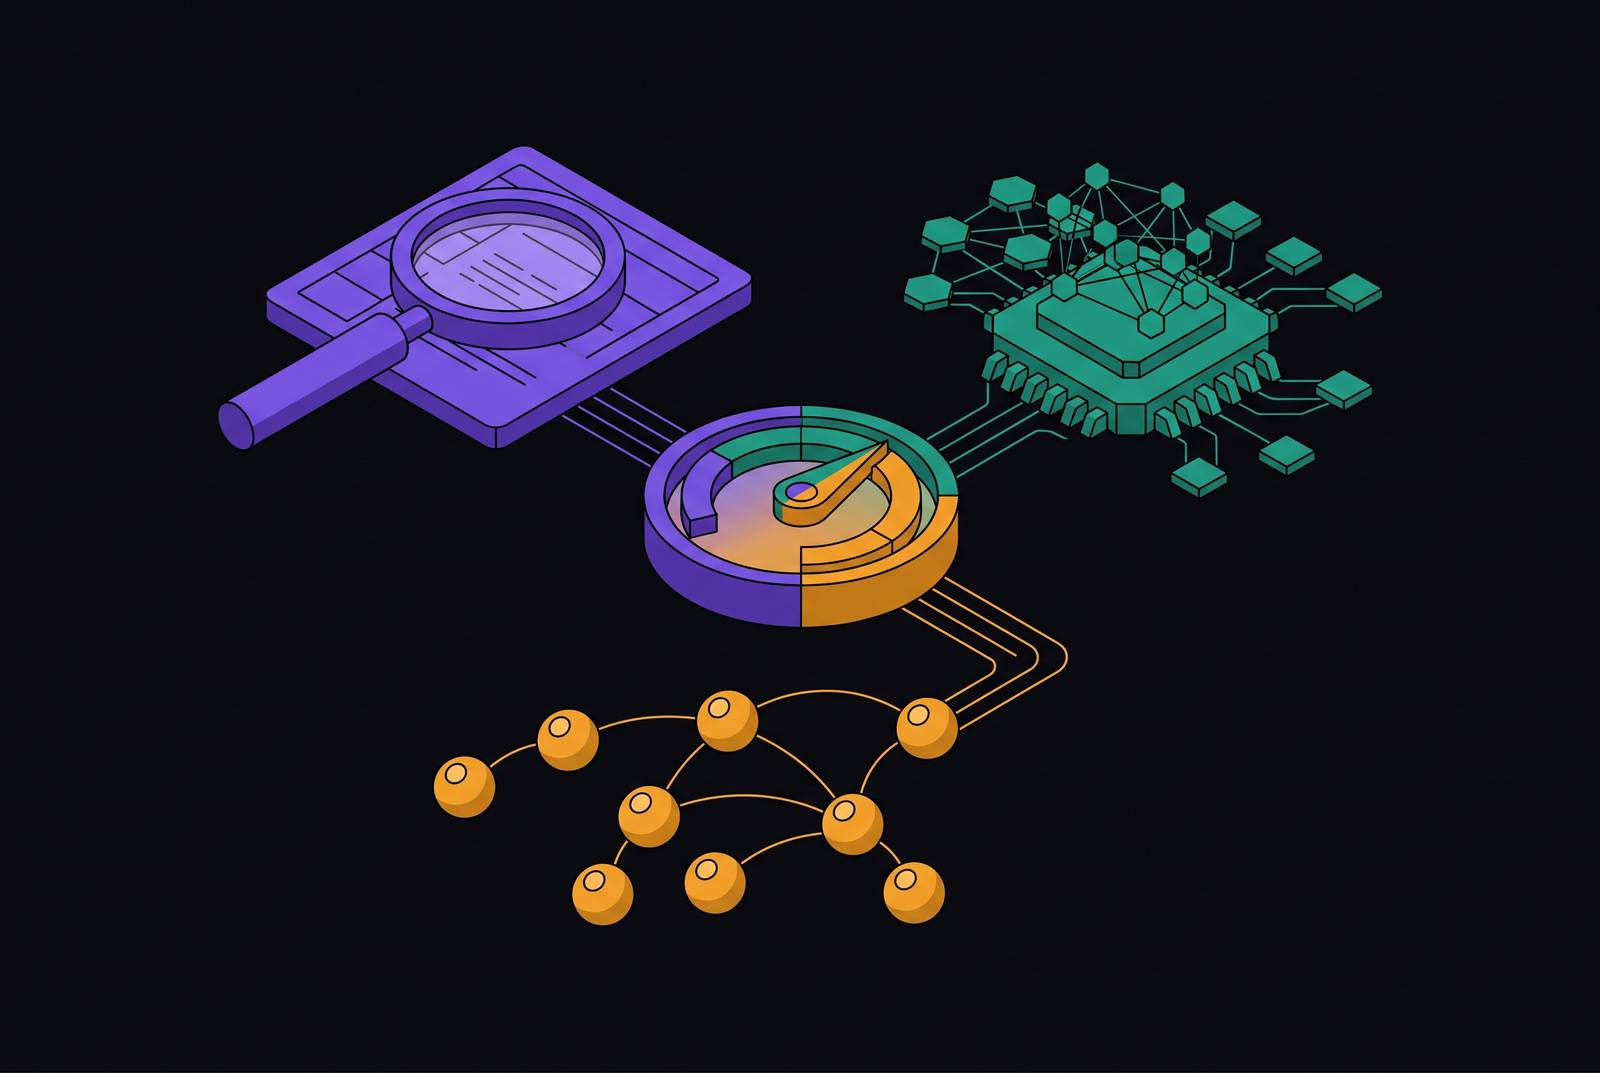
A multi-signal presence score measures three different evaluations of a business online, namely search engines’ recognition of its authority, AI systems’ ability to represent it, and human audiences’ expressed trust and attention. It goes beyond SEO and reviews by connecting those dimensions without treating them as interchangeable. The composite can guide action only when its component scores are visible, so teams can see where discovery breaks down and what needs attention first.
Why a single-channel presence score gives an incomplete and often misleading read
A brand can rank well in traditional search and still be absent from AI-generated answers. For buyers who get their answer from an AI system and never reach a results page, that search strength provides no exposure. A search-only score cannot reveal this absence. If presented as a measure of overall presence, it gives a misleading impression of how readily buyers can discover the business.
Public attention does not establish that an AI system will include the brand, just as AI inclusion does not establish positive human sentiment. Search rankings, social share of voice, and AI mention rate therefore measure separate phenomena. Strength in one can coexist with absence in another. The cost of a single-channel score is that it conceals the distinction between a business performing well where it is measured and being discoverable wherever buyers look.
What search visibility actually measures — algorithmic authority and structured discoverability
Search visibility measures whether a brand has built structured, machine-readable authority that ranking algorithms recognize. Indexed page coverage indicates whether its pages are available within the search index, while keyword breadth shows how widely its presence extends across queries. These are signals of structured discoverability. They describe a brand’s position within a system that selects and orders pages, rather than whether an audience trusts the business or an AI system can explain its relevance.
Structure, consistency, and link authority help build algorithmic credibility, and the search dimension shows how much recognition they earn. A strong result is meaningful within that scope. It does not, by itself, establish that a brand will appear in a synthesized answer, because selecting a page and representing a business are different tasks.
There is nevertheless an overlap between the systems. E-E-A-T, which stands for Experience, Expertise, Authoritativeness, Trustworthiness, originated as a search quality criterion and also functions as an AI inclusion criterion. The search dimension can therefore pick up evidence that contributes to AI visibility. That overlap is useful, but it is partial.
What AI visibility actually measures — how LLMs infer and represent a brand
AI visibility measures whether an LLM can infer who a brand is, what it does, and whether it belongs in a synthesized answer. In making that representation, the model extracts facts and assesses credibility across corroborating sources. Keyword match or link authority alone does not describe this evaluation. The available evidence must be assessed for whether it supports the brand’s inclusion in a response to a particular prompt.
Six core metrics make that question measurable. Brand Mention Rate captures how often the brand appears, while Recommendation Rate distinguishes appearances that endorse it as an option. Prompt Coverage addresses the breadth of prompts across which the brand is visible, and Share of Voice places that visibility in a competitive context. Model-Specific Visibility separates performance across models. Visibility Volatility captures variation over time, preventing a single appearance from standing in for a stable pattern.
Those metrics also need to distinguish three appearance states, which are simple mention, contextual explanation, and explicit recommendation. They are not equivalent forms of inclusion. A simple mention establishes presence, while a contextual explanation shows how the model represents the brand’s role or offering. An explicit recommendation goes further by presenting it as a choice.
The evidence supporting these appearances includes entity clarity, content structure that permits verbatim extraction, and corroboration across credible third-party sources. E-E-A-T applies to more than the brand’s own pages here. Author bios with credentials provide on-page evidence, while references in authoritative publications provide off-site evidence about the same brand. Because inclusion is model-specific and can change, visibility metrics are estimates based on repeated prompt sampling. A prominent appearance in one model does not establish visibility in another, and a single answer cannot reliably characterize either.
Why AI visibility cannot be read off search performance alone
A search score mainly shows how visible the brand is in ranked results, while an AI answer can use third-party evidence about the brand. Listing sites such as Yelp, TripAdvisor, and MapQuest illustrate that distinction. The business can be represented through sources other than its own domain, so measuring only the domain’s search performance leaves part of the evidence base unmeasured.
Organic position is not a dependable substitute for observing citations either. Pages outside the organic top ten can be cited by AI systems when they provide strong authority signals. A page’s location in search results does not settle whether its information will be selected for a synthesized answer, and a high ranking cannot establish how the brand will be described.
AI visibility needs to be tracked independently of search scores. Search performance can show algorithmic recognition, but only observation of AI answers can show whether a model mentions, explains, or recommends the brand. A multi-signal framework preserves that boundary so that an unmeasured dimension is not mistaken for a healthy one.
What social and human-consensus signals actually measure in a presence score
Social and human-consensus signals capture how people talk about a brand, including the attention it receives and the sentiment attached to it. This dimension includes brand mention volume, share of voice within a category’s conversation, and sentiment across social platforms, forums, review sites, and earned media. Reviews are only part of that evidence. Neither a ranking algorithm’s recognition nor an LLM’s representation can fully substitute for the live, human-generated conversation around a business.
Visibility is exposure, or how often the brand appears, while awareness concerns recall. Exposure can feed awareness without measuring it directly. A presence score based on mentions can therefore describe how frequently a brand enters the conversation, but it should not present that frequency as proof that people remember it.
Volume also needs sentiment to become interpretable. People may talk a lot about a brand in a negative way, while the few comments about a rarely mentioned brand may be strongly positive. Neither volume nor sentiment is sufficient alone. What gets measured is another limit, because untagged product images can contain visual mentions even when the brand name never appears in text. Text-only monitoring misses that exposure, leaving a gap in its account of public attention.
Human consensus also feeds back into AI perception. Narratives in high-authority publications and forums can become part of the training and retrieval data that shapes how LLMs represent a brand. Weak human-consensus signals today can help lead to weak AI visibility tomorrow, though a social score and an AI answer still measure different things at the same point in time. This feedback is why social belongs in the analytical framework.
How do you get a complete picture from search, AI, and social together?
The analytical value of the composite lies in the relationships among its components. A brand may be strong in search authority and human consensus but weak in AI inference confidence. That pattern differs from a brand with broad visibility but negative public sentiment. Each combination points to a different constraint. A composite score is therefore an actionable unit only when it preserves the profile beneath the total, allowing the team to distinguish a discovery gap from a trust problem.
Consider a brand with a low AI mention rate and strong search authority. The contrast suggests a need to examine entity clarity and third-party distribution. Strong rankings have already established one kind of recognition. The AI component provides the evidence needed to investigate why that recognition does not translate into AI inclusion. Without the component view, a blended average could make the same brand appear broadly healthy.
Share of voice is a useful place for small teams to start because it shows whether public evidence around a brand is growing stronger compared with its category. Yet it cannot establish structured discoverability or model-specific inclusion. A wider framework gives that signal its context. Categories including Brand Recognition, Market Score, Presence Quality, Brand Sentiment, and Share of Voice can separate different aspects of presence.
Evident is a natural illustration of the principle that the composite score should serve as the unit for decisions. The relevant standard is visible component scores that connect the overall assessment to a specific gap. Breadth alone is not the deciding criterion. For tools that combine social engagement, citations, reviews, and SEO into one presence metric, usefulness depends on whether the combination explains where the business is weak.
What makes a multi-signal score genuinely diagnostic rather than decorative
A diagnostic score identifies which dimension is lagging and exposes enough signal-level detail to indicate what needs attention first. “Low presence” is not a sufficient diagnosis. Low AI mention rate despite strong search authority is more useful because it narrows the problem to a particular form of evaluation. Negative sentiment amid high mention volume points to a different problem that more exposure alone would not solve.
The strongest objection to composite scoring is that its inputs are heterogeneous. Search coverage, sampled AI appearances, and human sentiment do not describe the same event or share the same uncertainty. Aggregation can hide those differences. Preserving component visibility and tracking trend direction avoids treating any point-in-time number as definitive. A total can orient the reader, but the underlying measurements must remain available to support the decision.
AI measurement makes this requirement especially clear. Its probabilistic outputs require repeated sampling over time and per model, rather than exact-looking conclusions drawn from a single answer. A one-time audit provides only a snapshot. Ongoing monitoring is necessary to distinguish a persistent gap from volatility and to show whether an intervention is associated with improvement. Structured, repeatable measurement processes are more useful for that purpose than an unusually strong one-time score.
The score must identify the weak dimension, provide enough detail to support a targeted intervention, and be measured frequently enough to show whether that intervention is working. This is what separates a decision tool from reporting theater. Measurement must precede optimization, because the business first needs to know whether buyers cannot find it, AI systems cannot confidently represent it, or public conversation gives people reasons not to choose it.
Sources
- AI Perception Index 2026 How Large Language Models Position Brands in the AI Era by Faruk Tugtekin :: SSRN
- Cross-Platform Entity Signals: sameAs Schema, Multi-Platform Presence, and Knowledge Graph Integration — SIGI
- From Stochastic to Stable: Rank Stability and Structural Sufficiency in AI Visibility Measurement
- Generative Engine Optimization at Scale: Measuring Brand Visibility Across AI Search Engines
- Measuring brands in machine answers: A scoping review and validity framework for large language model brand-visibility audits
- From Prompt to Recommendation: A Fitted Stage Model of Brand Visibility in AI Search