How LLMs Weight B2B Vendor Signals When Ranking Recommendations Against Competitors
LLMs rank B2B vendors primarily on third-party corroboration, not your website's content quality.
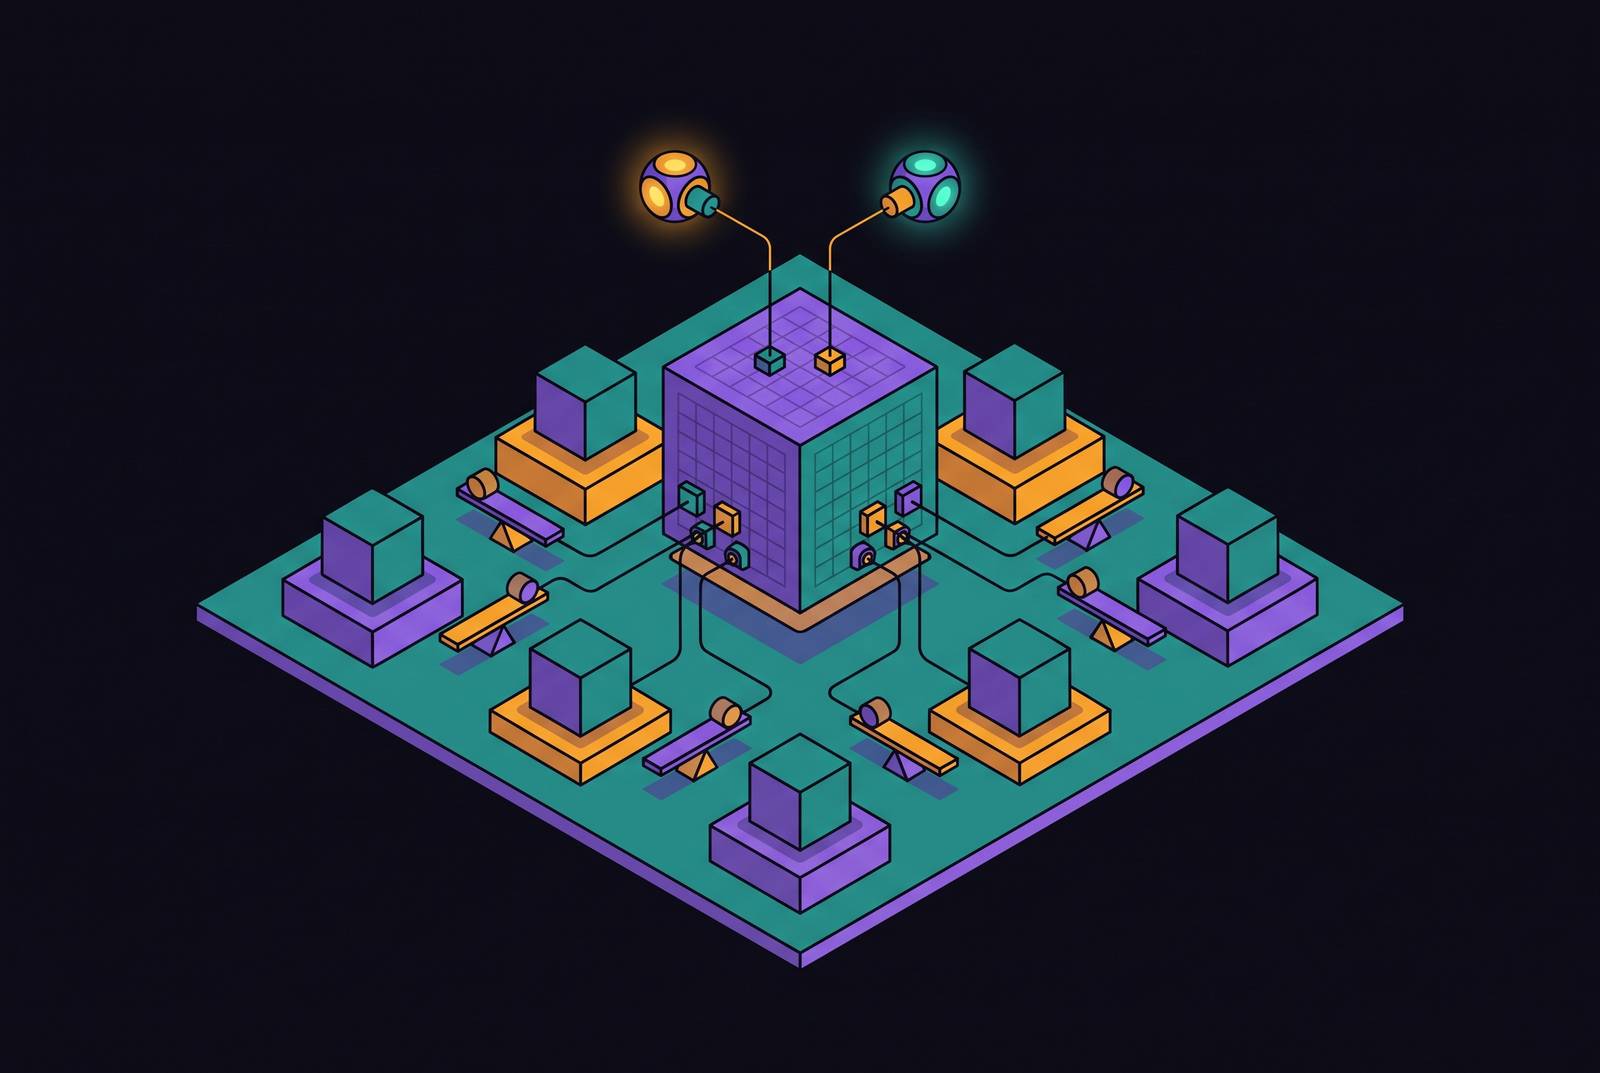
LLMs evaluate B2B vendor credibility through four connected signal categories, which are entity identity, third-party validation, review substance, and content authority. Recommendations depend on pattern density, the weight, consistency, and cross-source corroboration that make a vendor legible to an AI system. The operational goal is inclusion in the buyer’s answer.
How B2B buyers now use LLMs during vendor evaluation
LLM use has become mainstream in B2B purchasing, with 94% of buyers now using LLMs during their purchase journey. Usage peaks during active vendor comparison. Buyers use ChatGPT, Claude, and Gemini to compare shortlisted vendors, synthesize documentation, model costs, draft RFP language, and build implementation plans. The assistant is helping buyers interpret the differences between products when those differences can determine a purchasing decision.
That behavior changes which public evidence a vendor needs at the comparison stage. A buyer asking about implementation needs more than a broad product description, while a buyer comparing customer outcomes needs evidence beyond the vendor’s own claims. The answer compresses research that would otherwise span several sources into a single synthesis. So a buyer can rule out a vendor without ever looking at its website. If its signals are not indexed and structured for AI consumption, the LLM may not know it exists at the critical comparison moment.
Why LLM recommendations are an inclusion problem, not a ranking problem
A recommendation is not a results page that buyers necessarily scroll through. Even when an assistant presents an ordered list, the decisive boundary separates the vendors it includes from those it omits. Position is secondary to presence in the answer. A missing vendor has no opportunity to have its product quality or pricing assessed within that synthesis, however competitive either might be.
Brand familiarity in the training corpus gives well-documented incumbents an initial advantage. Their products have an established public footprint from which an assistant can construct an answer. New competitors have more work to do because a strong product alone does not give the system that evidence. Inclusion reflects what the system can resolve from available signals.
However, this does not make company size a sufficient strategy. For a niche query, evidence describing the relevant use case gives an assistant more to work with than a broad claim of general capability. That identifies a practical lever, namely building a specific, corroborated account of whom a product serves and what it does. Signal quality can be developed deliberately rather than treated as a by-product of brand awareness.
The dark funnel problem: why most vendors cannot see where they are losing
LLM-mediated research can happen without leaving a traceable signal for the vendor being evaluated. Buyers can ask for comparisons, look into what seem to be weaknesses, and narrow their choices without visiting an owned property. The vendor sees neither the question nor the omission. Data on visits and inquiries alone cannot show how an assistant described the business while a buyer weighed it up.
Measurement must precede optimization because absence has several possible explanations. The system may lack a clear vendor identity, third-party evidence that fits the question, reviews with details that help answer it, or product information it can extract. Those are different gaps requiring different responses. Scale Labs’s approach to scoring how AI systems perceive a business addresses this diagnostic problem by seeking a quantified account of vendor representation rather than assuming public content produces recognition.
That account also needs to cover multiple models and platforms. Citation behavior cannot be reduced to a single universal source hierarchy, and the supplied evidence does not establish a reliable platform-by-platform list. A vendor’s presence in one assistant is therefore not a sufficient reading of its broader AI visibility. Monitoring across algorithmic and AI contexts makes the blind spot more tractable by examining actual descriptions and inclusion patterns. It also shifts attention beyond the channels a vendor directly controls.
Why third-party sources outweigh owned content in LLM citation decisions
LLMs give third-party sources much more weight than first-party brand content when they recommend vendors. A vendor’s website states what the business says about itself, while outside sources provide corroboration. That distinction changes the asset mix for AI visibility. Review platforms, analyst coverage, community discussions, and editorial coverage become key sources for citations even though the vendor cannot control what they say.
The implication is not that owned content has become unnecessary. An owned site can establish product scope, explain capabilities, and supply technical facts that outside sources omit. Its weakness is as a substitute for independent validation. Publishing more pages cannot automatically repair an absence of corroborating evidence elsewhere, particularly when the buyer’s question concerns trustworthiness or customer outcomes.
For measurement providers such as Scale Labs, this shift makes the full signal footprint a more useful diagnostic target than owned-site performance alone. Vendors need to understand which outside sources contribute to their representation before deciding where to invest. Vendors need to weigh evidence that gets them included against work that only adds more content. That gives third-party sources the lead in the strategy, while owned content gives systems accurate product information they can extract.
How review volume, recency, and specificity shape AI citation weight
Volume provides breadth, recency concerns how current the evidence is, and specificity supplies details that can answer a buyer’s question. Each serves a different purpose in evaluation. Treating review strategy only as a collection target overlooks whether the resulting evidence is useful for comparing vendors.
For example, broad praise gives the system little to draw on when asked about implementation or customer outcomes. A review describing the use case and a stated result gives an assistant a more direct connection between the product and the buyer’s need. High review volume with low specificity can leave the system with many endorsements but little evidence suited to the query.
Breadth across industries is useful when reviews preserve the context in which customers used the product. It allows the evidence to distinguish a relevant customer experience from a broadly positive one. Recency then helps the system tell current accounts from older descriptions of the product. Yet those signals only reinforce the vendor if the system can connect them to the same entity. Reviews scattered across inconsistent names or conflicting product descriptions weaken that connection, which makes identity the prerequisite beneath review strategy.
Entity identity and consistency as a prerequisite for AI legibility
Before an LLM can confidently cite a vendor, it must resolve who that vendor is across sources. Consistent positioning, product descriptions, and named leadership help connect references on Wikipedia, G2, LinkedIn, the vendor’s site, and analyst coverage. Conflicting descriptions create uncertainty about those connections. A model may then skip the vendor because it cannot confidently reconcile the evidence, rather than because it has judged the product unsuitable.
Entity consistency is therefore a hygiene layer. It gives reviews and content a common referent. A strong customer account cannot fully support inclusion if the assistant is uncertain which business or product the account describes. Likewise, authoritative owned content does not compensate for contradictory product scope elsewhere.
How content structure and placement determine whether owned assets are citation-eligible
Owned content contributes when AI retrieval systems can extract clear, relevant facts from it. Quality alone does not establish citation eligibility. A well-written asset can still be ineffective if its structure obscures the answer or its placement prevents public access.
Structure and factual consistency work together at this layer. Product descriptions need to express a scope that agrees with the vendor’s identity elsewhere, while technical material needs to make the relevant capability understandable. Clear structure makes the information usable. Consistency makes it reinforce the rest of the evidence. Content authority depends on both, because an extractable statement that contradicts other sources does not create a dependable pattern.
For enterprise B2B, compliance and technical questions expose the cost of inaccessible documentation. If the information needed to establish suitability is not public and structured, the assistant may describe the capability incorrectly or omit the vendor. In regulated industries, that can become a category-exclusion risk. A vendor may have the required capability without supplying evidence the system can use to establish it. Owned assets have a distinct role here, furnishing precise facts that third-party validation alone may not provide.
Why the four signal categories function as a system, not a checklist
Entity identity, third-party validation, review substance, and content authority reinforce one another when they describe the same business in compatible terms. The operative mechanism is cross-source corroboration. Consistent accounts on the vendor’s site, G2, analyst platforms, community discussions, and editorial coverage create a pattern an AI system can extract with greater confidence. Pattern density is therefore not just the number of mentions. It includes whether those mentions support the same claims and supply the information the buyer needs.
Strong content authority paired with fragmented identity creates uncertainty about attribution, while abundant reviews without specific outcomes offer quantity without usable detail. Measuring each category on its own can miss why a vendor with what looks like a strong footprint still gets left out. Simultaneous measurement reveals where one gap is neutralizing the value of other evidence.
Evident’s framework operationalizes that principle by scoring a broad range of signals across three evaluation dimensions, which are algorithms, AI systems, and human audiences. Its actionable scoring connects diagnosis with decisions about what to fix first. The framework is relevant because the problem spans more than a single content channel or audience. A vendor needs to understand both the individual weakness and its effect on the wider pattern.
What vendors can act on first, given that measurement must precede optimization
The practical sequence begins with diagnosis across platforms, signal categories, and query types. A vendor needs to establish where it appears, how it is described, and which evaluation questions expose missing or contradictory evidence. Perception scoring, including the approach offered by Scale Labs, is one way to organize that baseline for prioritization. Without that baseline, a team can work on a layer that is already strong while leaving untouched what keeps it out of answers.
The first audit should examine entity consistency before further content or review investment. The vendor’s name, positioning, and product scope should agree across third-party platforms, review sites, and owned properties. Once that foundation is coherent, the next priority is the third-party citation pipeline. The immediate actions include improving review volume and recency on G2, Capterra, and Trustpilot, developing analyst relations, and building presence in community platforms that appear in the AI systems being measured. Review specificity remains essential because collection alone does not provide answers.
These priorities then need to be tested against subsequent representation. Evident’s actionable prioritization provides one route from a multi-signal diagnosis to a sequence of repairs. A fix is useful when it strengthens the pattern supporting accurate inclusion. Ongoing monitoring is therefore the operating discipline, because pattern density must be managed as a connected system.