Author Entity Signals and Their Effect on AI Brand Citation Likelihood
AI engines trust named, verifiable authors far more than domain strength.
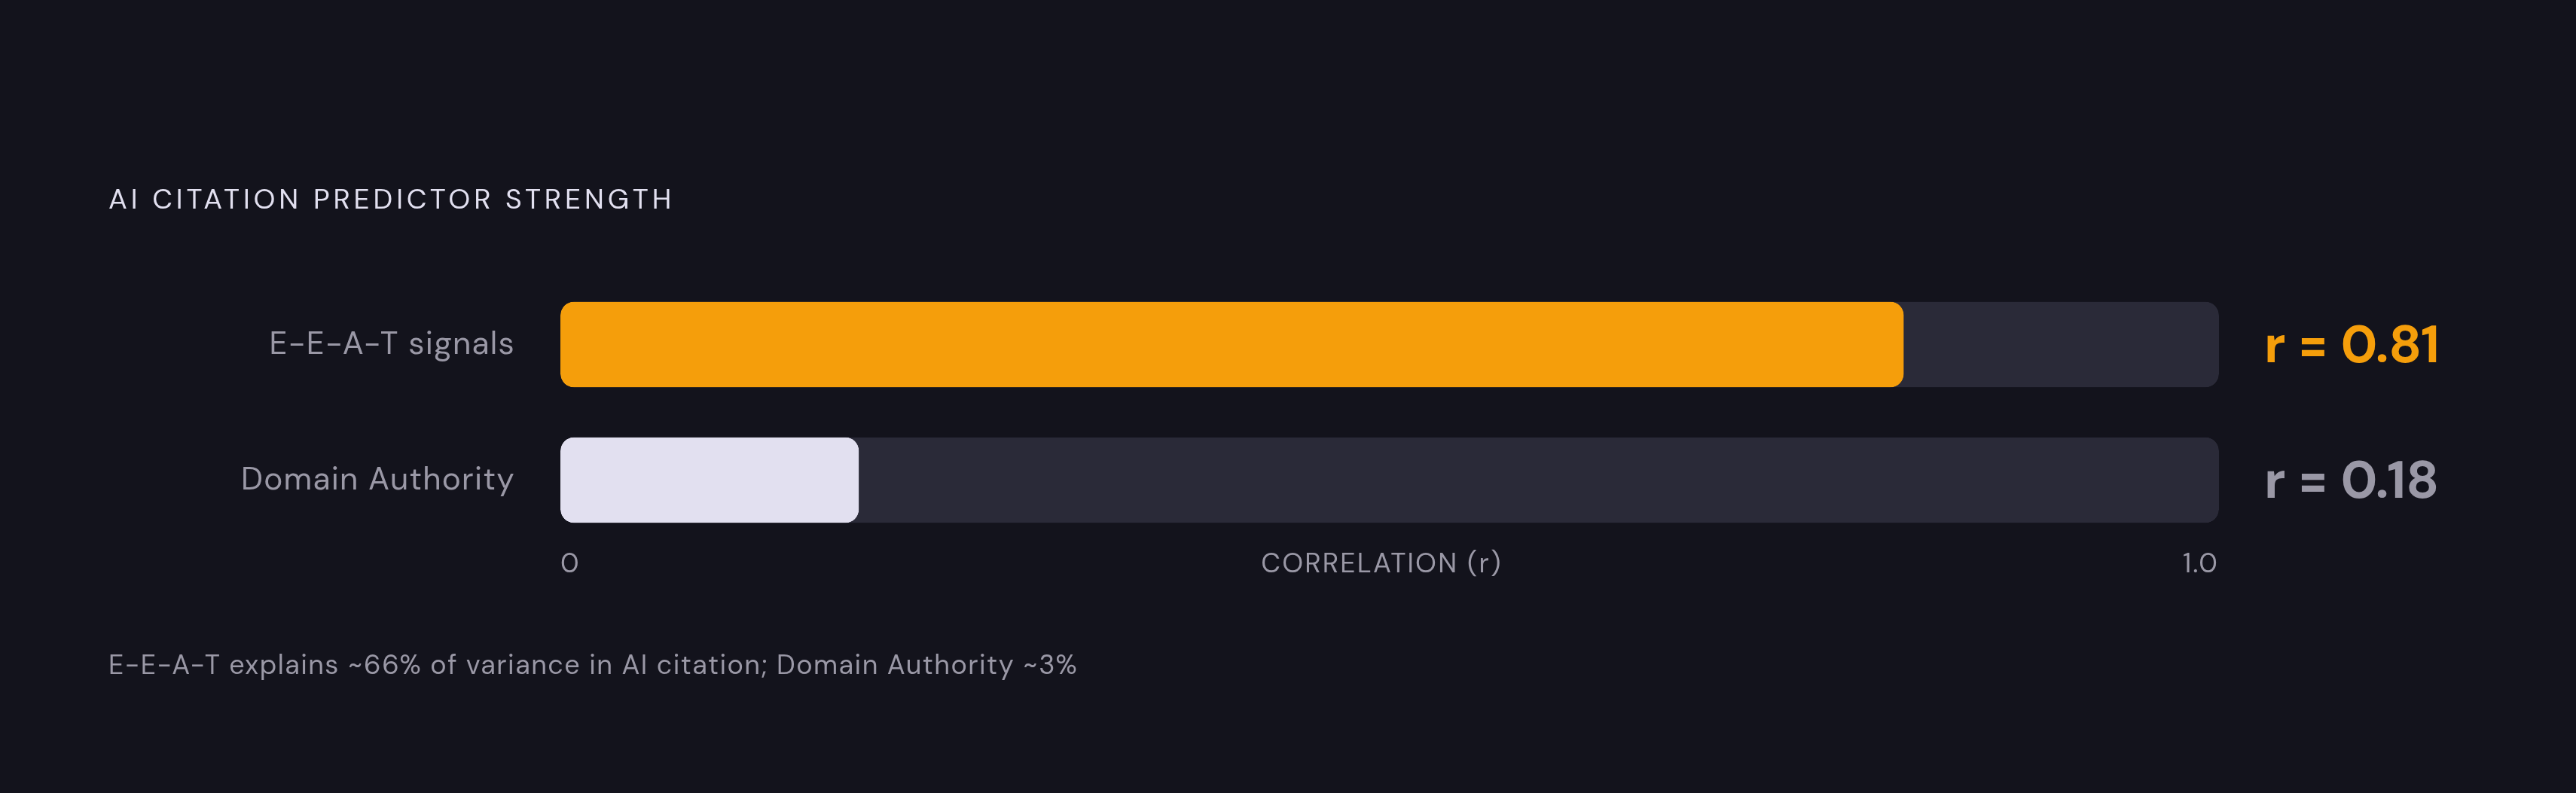
Most teams chasing visibility in AI search still reach for the same lever they pulled for a decade: raise Domain Authority and the citations will follow. That instinct is wrong, and the data on it is not close. AI systems and traditional search engines run on fundamentally different trust mechanisms. The metric that predicts organic rankings barely predicts AI citations at all. Domain Authority correlates with AI citation at r=0.18, which puts DA's explanatory power at roughly three percent of the variation in whether an AI engine decides to cite a brand, a correlation too weak to build a strategy on. E-E-A-T signals, measured in the same analysis, correlate at r=0.81, and that gap is wide enough that if your team is still pouring effort into DA instead of entity signals, you're spending your budget wrong.
The reason for the gap is architectural. A search engine trusts a domain. An AI engine trusts an entity: a person with verifiable credentials, a presence across more than one platform, and corroboration from sources that have no stake in the brand's success. Domain Authority was built to model link equity accumulated by a website as a whole. It says nothing about who wrote a given page, whether that person can be verified as a real practitioner, or whether anyone outside the brand's own channels vouches for them. An AI engine answering a question is deciding whose claim to repeat, and it needs an answer to "who is saying this" before it can decide how much to trust what they said.
That difference carries a direct operational consequence. When a team treats generative engine optimization as SEO with a new name, still iterating on backlink counts and domain-level metrics, it optimizes for a signal the model barely reads. The framework that predicts citation runs through the author: credentials, cross-platform presence, and third-party corroboration attached to a named person. That's the signal hierarchy the rest of this piece maps in detail.
The entity evaluation model AI engines use to build trust in a source
An AI engine deciding whether to cite a source is running something closer to a background check than a keyword match. It does not evaluate a page in isolation. It assembles a representation of the brand and its authors from signals scattered across many locations and formats, then assigns a confidence score that governs how strongly it is willing to recommend what it finds.
Large language models cross-reference site data against verified global knowledge graphs, and when those external records agree with what a company says about itself and its authors on its own site, that agreement confirms identity to the model and lowers the odds the brand gets left out of a summary. Confidence scoring then shapes the language of the output directly: a high-confidence source gets definitive treatment ("X is excellent for"), while a low-confidence source gets hedged ("X might be suitable for"), so a brand can technically appear in an AI answer and still lose most of the commercial value of that appearance because the model won't commit to it.
The corroboration threshold sits at the center of this whole evaluation. AI systems weigh what independent sources say about a brand far more than what the brand says about itself, so a self-attestation scores roughly sixty to eighty percent lower on machine trust than externally corroborated entity signals. A page can say anything about its own author. A conference bio, an independent news mention, or a citation in someone else's research carries weight because someone else wrote it.
Brand name ambiguity compounds the problem, and most teams never see it coming. If a brand's name is also a common word, or if its messaging has shifted meaningfully in a short window, the model's confidence score drops, and it will favor a competitor whose identity it can resolve more cleanly. None of this is static, either. Reinforcement Learning from Human Feedback trains these systems to prefer responses that read as helpful, factual, and trustworthy, so sources that already appear often in high-quality training data accumulate stronger implicit authority over time, widening the gap between well-corroborated entities and everyone else.
The signal hierarchy: what predicts whether AI cites your content
If domain metrics barely register and entity signals dominate, the next question is which entity signals matter most, and in what order a team should build them. The evidence points to a three-tier structure: off-page mentions establish that the brand exists as a recognizable entity, author signals decide whether any individual piece of content is citable, and structural choices decide whether that content can actually be extracted and used once the model finds it.
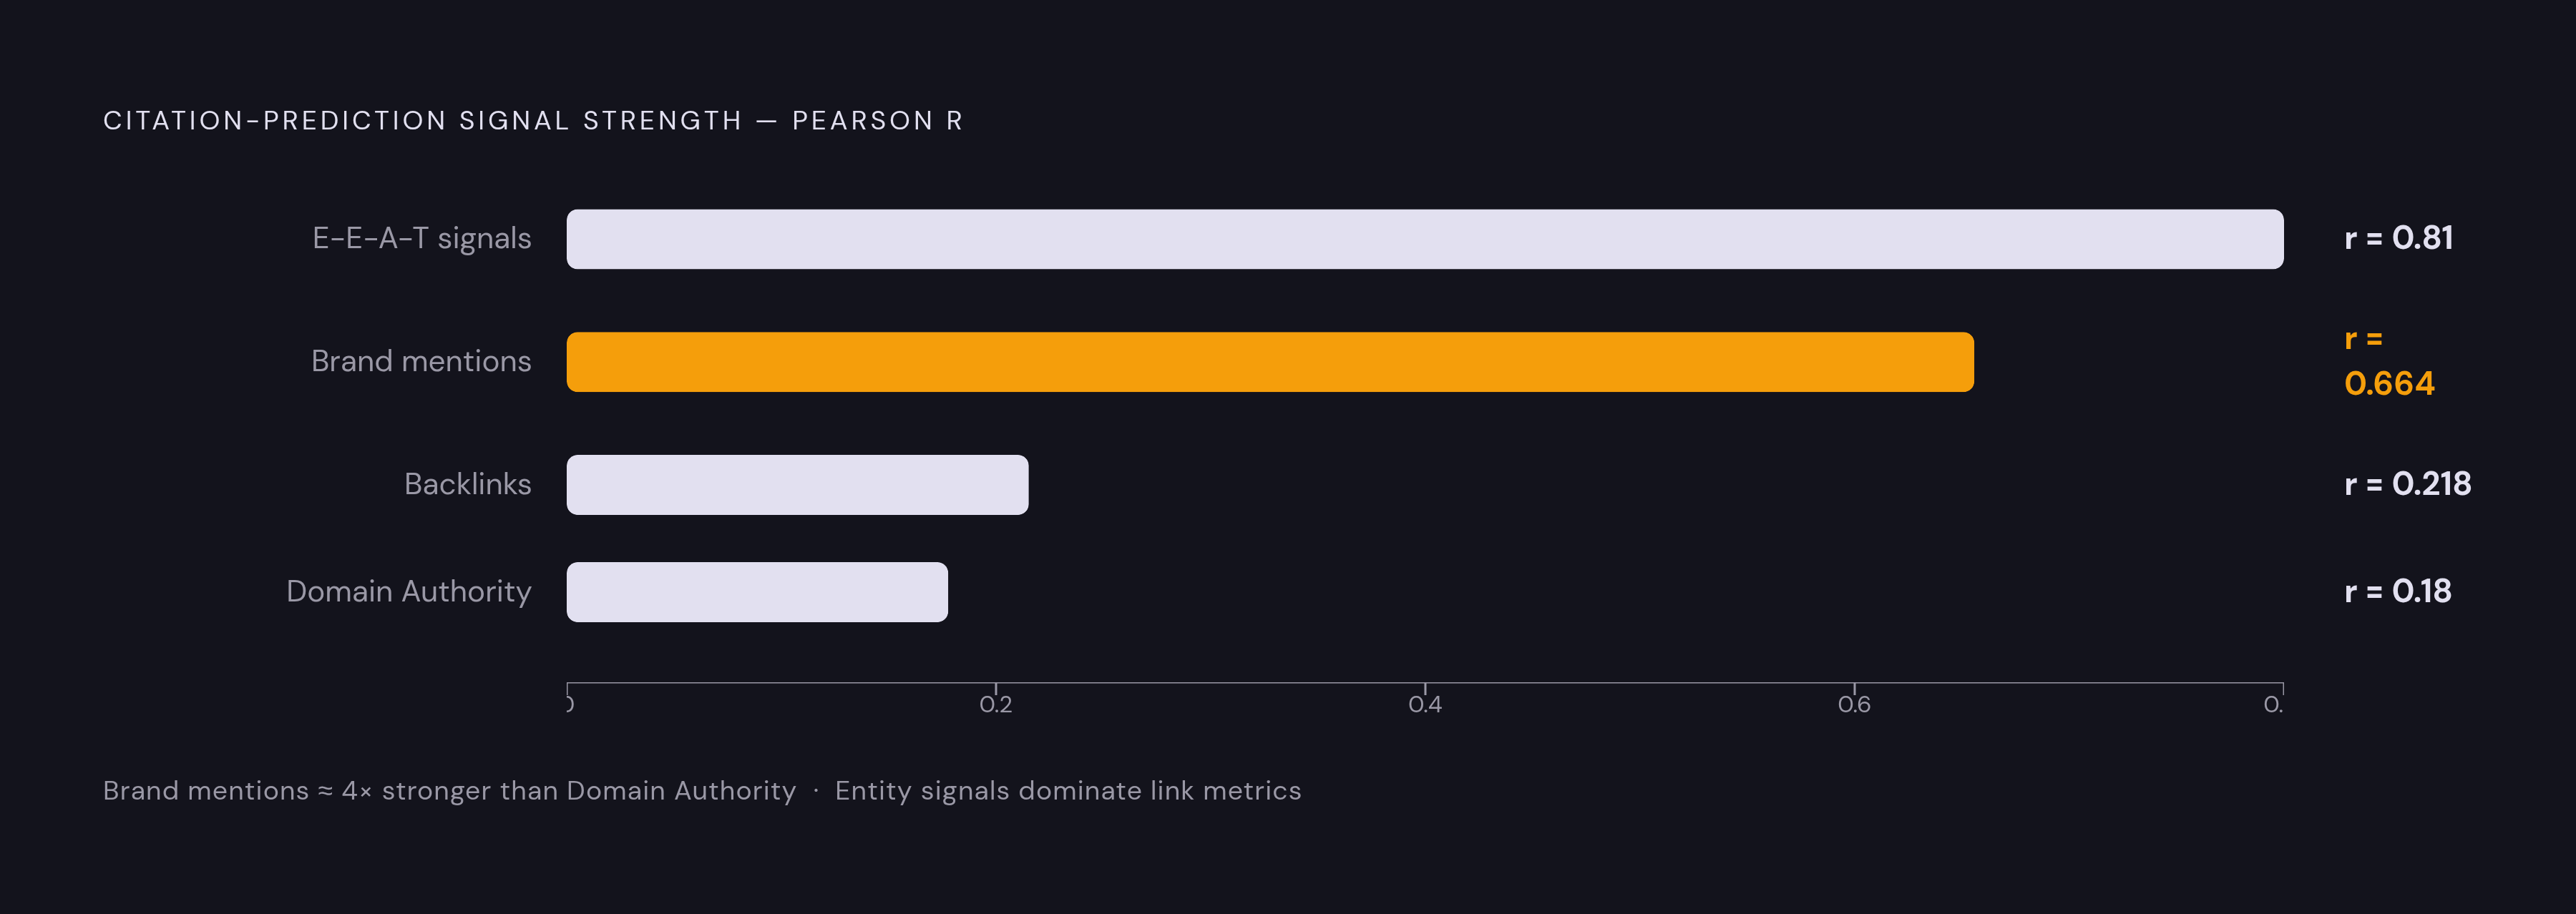
At the top of that structure, brand mentions across the web are the single strongest predictor of AI citation, and they outperform both backlinks and Domain Authority by a wide margin, but author-level signals remain the highest-leverage variable a brand can control directly on its own pages. An analysis of hundreds of thousands of pages and tens of thousands of citations found that brand mentions correlate with AI citation at r=0.664, about three times stronger than backlinks at r=0.218 and nearly four times stronger than Domain Authority at r=0.18. Consistent editorial coverage across publishers the model already trusts does more for this signal than any volume of outbound links, because the thing being measured is whether other people are talking about the brand, not whether they're pointing at it. Community platforms carry outsized weight here too: domains that accumulate heavy mention volume on Reddit and similar spaces see meaningfully better citation odds, since the model treats independent corroboration from unaffiliated voices as a stronger signal than anything the brand publishes about itself.
One tier down, on-page author signals decide whether a given piece of content earns citation once the brand clears the trust bar. When a named expert quote carries a real credential, a specific title at a specific company rather than a generic attribution, it produces a 40.9 percent lift in citation rates. Statistics paired with a named source, and inline citations pointing to authoritative references, add further lift on top of that, because together they build a chain of verification a retrieval system can actually follow from claim to source. Pages carrying visible author credentials outperform pages published under a generic "team" byline or an anonymous brand account by a meaningful margin, and most brands still haven't made that change.
The remaining tier is structural, and it governs whether content that clears both trust bars is even usable once the model retrieves it. Answer-first structure matters independently of everything above it: a large share of LLM citations are pulled from the opening portion of a page, so a correct, well-sourced answer buried beneath several paragraphs of setup will routinely lose out to a competitor who states the claim immediately. Length plays a role too, but only in service of depth. AI-cited pages tend to run considerably longer than typical web content, but word count by itself is not what the model is rewarding. What separates a long page that gets cited from a long page that gets ignored is original research and first-hand data, the kind of material that can't simply be found restated somewhere else.
Why each AI engine weighs author signals differently
Treating "AI search" as one system is the next mistake that follows naturally from fixing the first one. Each major engine runs its own retrieval and weighting logic, and author signals that dominate one engine's output can matter far less to another.
ChatGPT gets the dominant share of AI referral traffic across the ecosystem, so it is the highest-volume citation source for most brands, and it gives named author signals their largest reach there. Perplexity runs its own index and leans heavily on freshness, deprioritizing older material, and a notable share of what it cites doesn't appear in Google's own top results at all. Reddit and other community platforms make up a disproportionate share of Perplexity's top citations; independent community corroboration functions as a direct author-entity signal on this engine rather than a nice-to-have supplement. Claude leans on E-E-A-T signals more heavily than any competitor, with author credentials, stated methodology, and organizational authority correlating with citation probability at r=0.59, making it the most selective of the major engines on source credibility.
Google's AI Overviews and AI Mode apply E-E-A-T as a mandatory filter rather than a bonus layer: content missing clear E-E-A-T signals gets excluded before the rest of its qualities are even weighed, and the large majority of AI Overview citations trace back to sources Google already treats as authoritative. Oddly, the technical expression of author signals that practitioners most expect to help here, a complete Person and Article schema, has not shown the uplift most teams assume. The most rigorous study available found no meaningful citation gain from adding JSON-LD schema to AI Overviews, and a statistically significant 4.6 percent decline in citation rate after the schema was added. That result means structured markup functions as the technical scaffolding that carries author identity to the model, not as a ranking boost in its own right, and its absence or presence matters less than the underlying credibility it's meant to encode.
Because each engine weighs these signals differently, and because no brand can afford to build four entirely separate strategies, the signals to build first are the ones that transfer across all of them: a real, credentialed author, corroborated by sources outside the brand's own control. That's the throughline the rest of this piece turns into a system.
The three mechanisms for building author entity mass
Author entity mass does not accumulate from a single tactic executed well. It builds through three mechanisms that reinforce each other over time: consistent authorship systems, third-party validation, and proprietary data tied to a named individual.
The first mechanism, consistent authorship systems, is the structural layer. It means settling on one official format for an author's name, applying Person schema markup consistently, building a dedicated author hub page, registering an ORCID identifier where relevant, and keeping profile URLs stable rather than letting them shift with every site redesign. This layer gives an AI system a stable node to attach every other signal to. The technical version of this is a complete Person and Article schema that includes sameAs links pointing to authoritative external profiles, a LinkedIn page, a Wikipedia entry, an ORCID record, whatever applies. In plain terms, sameAs is the mechanism that tells a model "this author page, this LinkedIn profile, and this external citation all refer to the same person," collapsing what would otherwise look like several unconnected identities into one entity the model can reason about confidently. The minimum viable footprint for any author who wants to be legible to these systems runs across four places: the byline on the article itself, a canonical author page, the Person schema entity behind it, and at least one independent source corroborating that the person exists and does the work claimed.
The second mechanism, third-party validation, is what makes a signal more than a brand just talking about itself. It includes mentions in news coverage, academic papers, industry publications, and a listing in a Knowledge Graph. An author page that sits alone on a company blog is self-attestation. When that same author page gets independent profiles, contributed articles on outside publications, a conference speaker listing, and citations from other sources, it becomes something an AI system can actually inspect and weigh. An author mentioned across multiple independent platforms is meaningfully more likely to appear in AI responses than one who exists only on their employer's site. Concrete practical targets include bylines contributed to industry publications, interview appearances, speaker profiles at conferences, and LinkedIn content published under the person's own name, each one adding another corroborating node to the entity graph.
The third mechanism, proprietary data and named methodologies, is what generates the second mechanism at scale rather than waiting on it. When original research, a named index, or a methodology ties explicitly to an author, AI engines get something to cite that you can't find restated anywhere else. Once an author names and publishes an original study or index, that artifact becomes a magnet for citation: other publishers reference it, and those references are exactly the third-party mentions that feed the second mechanism. This is why original data sits near the top of the signal hierarchy. It is the engine that manufactures external corroboration on its own, rather than requiring a team to go chase that corroboration one mention at a time.
Implementing author entity signals: the four-signal priority stack
Four author signals deserve priority over everything else in this framework because they are directly actionable, measurable, and they compound across every major AI engine regardless of which one a given brand cares most about.
The first signal is a named expert byline carrying visible credentials. Use a real author's name wherever authorship is genuinely true, and put that person's role and relevant expertise near the claim itself, not tucked into a bio paragraph at the bottom of the page. Swapping out a generic "team" byline or an anonymous brand account for a real name and title is the lowest-effort, highest-impact change available, and most brands still have not made it. The named byline serves a dual function: it gives human readers a trust anchor and gives AI systems a named entity to attach the content's claims to.
The second signal is a dedicated author page built on structured data. Google's own documentation on Article structured data says to declare the author's name along with a URL or sameAs reference that uniquely identifies that person, and a ProfilePage schema makes the author, not the company, the main subject of that page. This is the mechanism described earlier made concrete: the author page becomes the canonical node, the sameAs links tie it to external profiles, and the Person schema turns the whole thing into something a model can parse rather than merely read.
The third signal is third-party corroboration you build deliberately rather than hope for. Contributed bylines in outside publications, interview appearances, conference speaker listings, and LinkedIn posts published under the author's own name each add an independent data point confirming the person is practicing and recognized beyond the brand's own channels. None of these need to happen at scale immediately. They need to happen consistently, because the model is reading for a pattern of outside recognition, not a single mention.
The fourth signal is original work tied to the author's name, whether that's a study, a named index, or a methodology the author originated and continues to publish under. This signal increases citation frequency by giving AI engines a citable artifact that cannot be found elsewhere, and every citation of that original work by an outside publisher becomes new third-party validation without requiring additional outreach. Built in this order, byline first, structured author page second, outside corroboration third, original work fourth, the stack produces an entity the model can verify at every layer it checks, across whichever engine a reader happens to be asking.
Sources
- Domain Authority vs AI Citation Authority: Why DA Predicts Less Than 4% of AI Citations · Clairon
- How LLMs Recommend Brands | Truelogic
- How to Get Cited by AI: Build LLM Authority Signals
- LLM Citation Analysis: How AI Models Decide Which Brands to Mention | RankinLLM
- How Do LLMs Choose Which Brands to Cite?
- How LLMs decide who to cite: The mechanics behind AI Search visibility
- ziptie.dev
- betteraisearch.com