Building a Repeatable AI Brand Audit Methodology
Brands must audit their AI visibility quarterly, not once.
Buyers now ask a chatbot before they open a search engine, and that change in order is why you need an AI brand audit, not just an optional experiment. A Salesforce survey cited by Wellows found that a majority of buyers consult AI before they buy, so this shift in behavior is already mainstream, not emerging. The mechanics of that shift matter as much as the adoption numbers. An LLM skips that step and hands over a short, confident shortlist instead, and The Rank Masters frames the consequence bluntly: a brand is either in that shortlist or it is not. There is no page two.
That shortlist carries weight because of how it gets generated. When ChatGPT or an AI Overview names a brand, the system is not neutrally retrieving a document, it is staking its own credibility on a specific recommendation, and users read that recommendation as authoritative rather than as one option among many. Researchers from Maastricht University, Utrecht University, and the University of Zurich tested this directly with the CONSUMERQ dataset: ChatGPT expresses a first-person product preference in 79% of its product-recommending responses. That figure confirms that the endorsement framing is not a loose metaphor; the model is doing something closer to vouching for a brand than listing it.
Vouching carries risk when the underlying information is wrong. A significant share of marketers already report that their brand has been misrepresented in an AI-generated response, and a meaningful fraction of those say the misrepresentation did real damage, to customer relationships, to sales, or to public relations. That inaccuracy is not random noise that will average out over time. It tracks back to specific, identifiable signals that AI systems weigh when they decide what to say about a company, and those signals are what the rest of this piece sets out to make auditable.
What AI systems read when they evaluate a brand
The signals that shape an AI system's opinion of a brand are specific and learnable, and none of them originate from the brand's own marketing copy.
That gap is most visible when comparing across model generations in a controlled test. What separated the brands that passed from the brands that failed was entity-level knowledge graph data, the structured record of who a company is, not which version of the underlying model happened to answer the question. Upgrading to a newer model does not fix a knowledge graph gap. Wellows looked at over 11 million AI citations and found that most brand mentions in AI answers trace back to third-party pages, not a brand's own domain, with most of those citations coming from listicles, comparison pages, and review roundups.
That finding lines up with a separate study from Ahrefs, which looked at tens of thousands of brands across ChatGPT, AI Mode, and AI Overviews and found that branded web mentions are the single strongest predictor of AI visibility, correlating roughly three times more strongly than backlinks do, meaning brands gain more from being named on other people's pages than from being linked to by them.
Where those mentions happen also matters. Community platforms, Reddit, YouTube, and Quora among them, account for a large share of the sources AI systems cite, and Wellows notes that relevance to the query frequently outweighs a domain's raw authority score, with a significant share of cited sources coming from domains that would never rank as authoritative by traditional SEO standards. A forum thread with the right specific answer can outcite a major publication with the wrong one.
The content of what gets said matters as much as where it gets said. An LLM does not process review sentiment the way a star-rating aggregator does. It reads the actual text of reviews, and it registers recurring negative phrases as a pattern, even when the numerical average still looks acceptable on paper. So if a brand has a slightly lower star rating but cleaner, more consistent sentiment in its written reviews, it can score higher on AI trust assessment than a competitor with a better number attached to worse language.
A brand has to exist as a recognized entity before any of these other signals can register, and that recognition is the basic precondition for all of them. Most AI-cited sources belonged to businesses with a verified Google Business Profile or a Wikipedia entry, so structured entity establishment is a prerequisite for AI visibility, not one optimization tactic among many.
Engine-level variation means one audit pass across one platform is not enough
Each major AI engine draws from a different pool of sources and produces a different answer to the same question, so testing a brand's visibility on a single platform produces a picture that is incomplete in a way that matters. Wellows' citation data shows that these engines agree on only a small fraction of the sources they cite. An audit run exclusively on ChatGPT tells a brand almost nothing about how Perplexity or Gemini describes it.
Non-determinism compounds the problem. The same brand can pass a prompt on one run and fail the identical prompt on the next, even on the same engine. In Friction AI's 40-brand study, individual brands flipped between PASS and FAIL across GPT-4o and GPT-5.2 on the exact same prompt, so one test run gives you closer to a coin flip than a measurement. Licensing arrangements between AI vendors and publishers also shape which sources surface in any given engine's answers, adding a layer of variation a one-platform audit cannot see around.
The most decisive argument for treating this as an ongoing process, not a snapshot, comes from how fast the underlying source pool itself moves. Wellows found that roughly two-thirds of the sources cited by AI systems change within a two-week window. A brand audit run once a year, or even once a quarter and then filed away, measures a landscape that has already shifted substantially by the time anyone reads the report. Quarterly is the floor, not a cautious cadence.
The four-step framework for running a repeatable AI brand audit
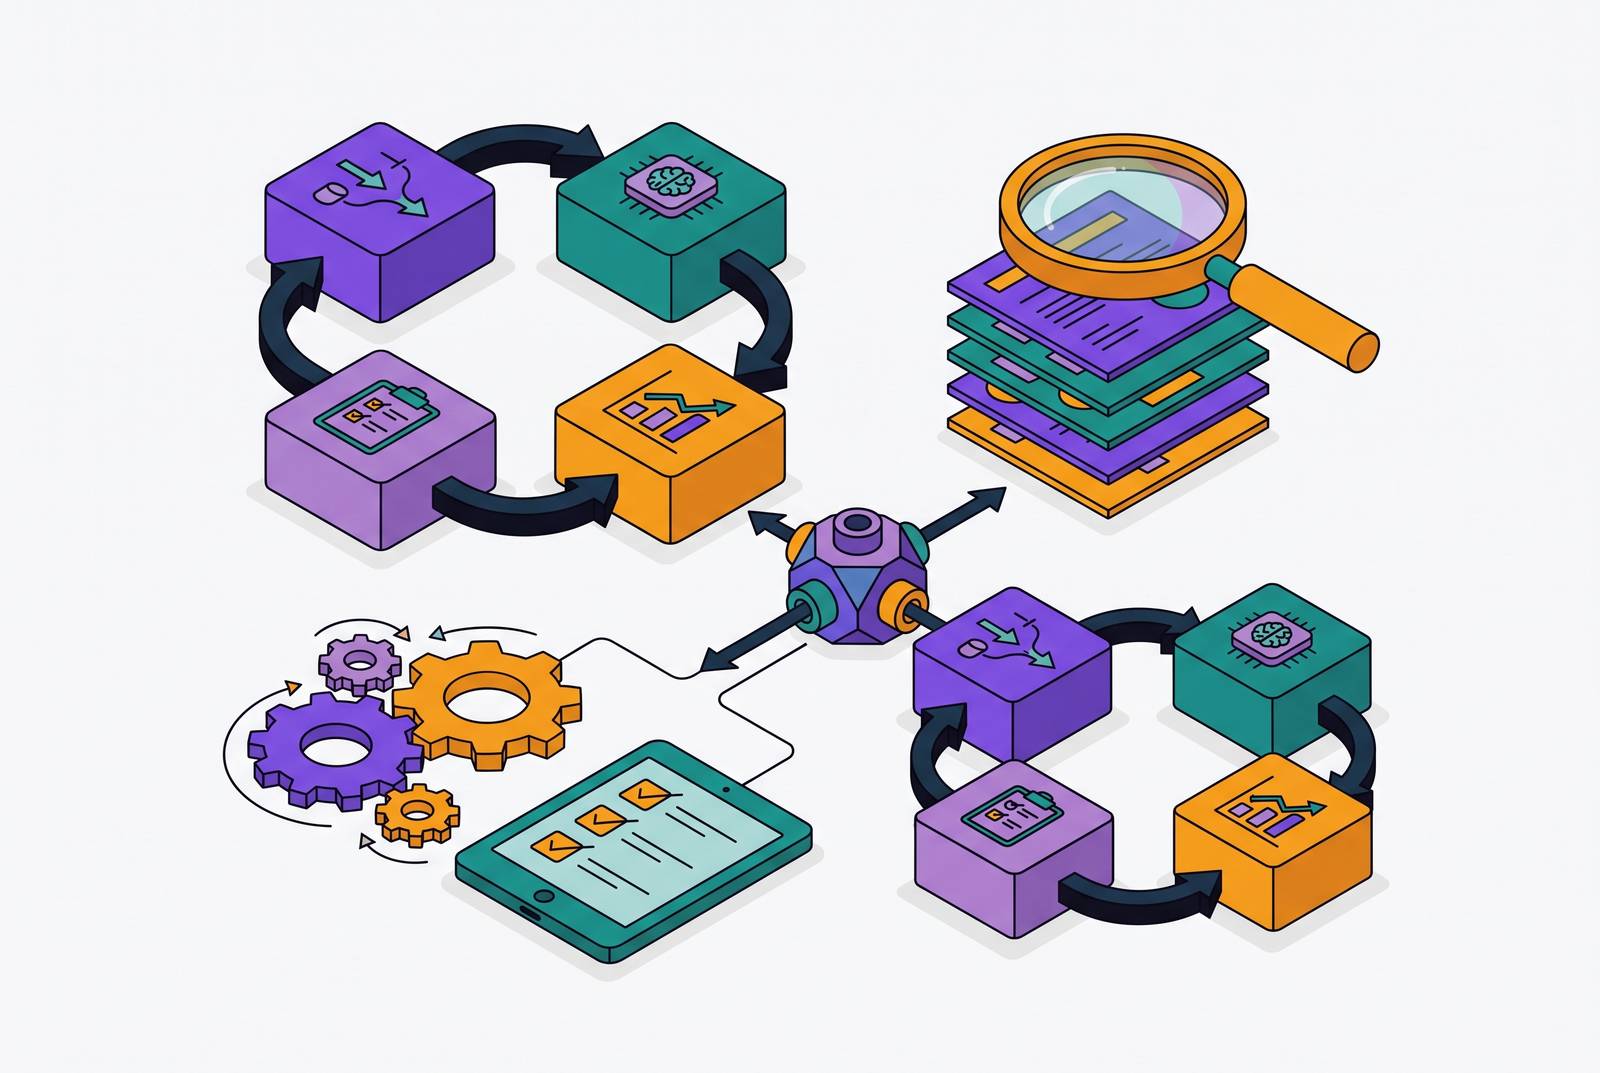
A repeatable AI brand audit runs through four steps in sequence: prompt design, multi-engine execution, layered analysis, and fix-then-repeat, carried out at minimum once per quarter rather than as a single diagnostic exercise.
Prompt design starts by organizing test questions across three distinct diagnostic layers, which Friction AI's framework separates into entity recognition, which asks whether the model can identify the brand at all; category visibility, which asks whether the brand surfaces in relevant category-level queries; and recommendation share, which asks whether the brand gets named at the moment a buyer is ready to choose. Fifteen starter prompts, five per layer, cover this range well enough for a first pass. Entity-layer prompts look like "Who is [brand]?", "What does [brand] do?", and "What is [brand] known for?", while category-layer prompts look more like "What are the best [category] tools for [ICP]?". Savage Audit adds a complementary structure built around buyer intent rather than marketing language, recommending five prompt classes: category discovery, brand research, comparison, problem-solution, and trust/proof. You need to run each prompt three to five times per engine, because one run only catches noise, and runs vary this much.
Execution comes next, and it has to span multiple engines by design. Running prompts across at least ChatGPT, Perplexity, and Gemini is the minimum bar, since the limited overlap in sources between engines means results from one cannot be extrapolated to predict another. Savage Audit recommends logging results in a structured capture table: whether the brand was mentioned, the exact language the model used, which competitors got named alongside it, what claims were made, and which sources or citations appeared in the response. This stage should capture raw descriptors only. Summarizing or interpreting the findings at this point throws away detail that the next step depends on.
The third step is layered analysis: working out which of the three layers is actually failing. If the model cannot recognize the brand as an entity at Layer 1, everything else is moot. Every dollar spent optimizing Layer 2 content or Layer 3 citations is wasted if the model cannot resolve who the brand even is, Friction AI finds. Layer 2 analysis checks whether the brand shows up in category-level queries and how accurately the model describes it next to competitors. Savage Audit recommends building out three separate competitor groups for this comparison: direct competitors, search competitors, and AI-answer competitors, the last group being the aggregators, listicles, and brands that surface specifically in AI category prompts, which are often not the same companies a brand's own team would name as its competitive set. Layer 3 analysis turns to the citation and source gap: which publications, reports, and review sites the AI draws from most often, and whether competitors consistently appear in those preferred sources while the brand in question does not. No amount of website editing will fix that, because the pattern signals a structural citation bias. At this stage, you need a source audit that checks specifically for presence on community platforms like Reddit and Quora, in review roundups, and in comparison listicles, since those are the source types that dominate AI citations.
The fourth step is fixing the layers in sequence and then repeating the whole process. Fixing Layer 1 first means securing a verified Google Business Profile, a Wikipedia presence, and consistent brand terminology used across the web, before any money goes toward content or PR. Layer 2 comes next: correcting hallucinated or outdated descriptions through structured data, an LLMs.txt file, and brand pages formatted consistently enough for models to parse reliably. Layer 3 comes last: building the citation footprint itself through digital PR, earned media, and a genuine, sustained presence in the communities AI systems already draw from. Sources turn over fast, so quarterly is the minimum re-run cadence, but if a team has the resources to sustain it, Wellows' finding that 65% of cited sources change within two weeks argues for continuous monitoring over a once-per-quarter snapshot. Running this manually, across three or more engines, with three to five runs per prompt and fifteen prompts per brand, adds up fast.
Scoring what the audit surfaces, the signals that move from measurement to a priority fix list
Raw audit output, a list of mentions, descriptions, and citations, only becomes useful once it gets scored against consistent signals that let a team rank fixes by which gap is actually costing deals. The measurable dimensions to score are mention presence (is the brand named at all), sentiment accuracy (is the description positive, neutral, or negative, and is it factually correct), category clarity (is the brand placed in the right category), differentiation (are the right attributes attached to it relative to competitors), and citation footprint (does the brand appear in the source types AI systems prefer).
A complementary way to score the underlying trustworthiness of a brand's sources is the Human Authority Score framework, which identifies five signals that AI systems use to judge whether a source is worth citing: Experience, Recognition, Consistency, Citation Velocity, and Human Proof. Together, these five signals answer a single question for the model: can it vouch for this source if it cites it?
Wellows breaks the drivers of LLM brand visibility down into ten specific factors, split cleanly into two categories. One category covers signals a brand controls directly on its own properties, content structure, structured data, entity recognition, and consistent terminology. The other covers signals earned entirely off a brand's own properties, third-party mentions, citation frequency, source authority, user-generated content, review platforms, and digital PR. Scoring needs to keep these two categories separate rather than blending them into one composite number, because a brand with strong on-site signals but weak third-party corroboration needs a different fix than a brand with strong mentions everywhere but inconsistent entity data underneath them. Those are two different problems with two different fixes, and collapsing them into a single score erases the distinction a team actually needs to act on.
Share of voice, how often a brand appears across a fixed set of target prompts relative to its named competitors, is one output metric worth tracking on its own. You can track it quarter over quarter without proprietary tooling, using nothing more than the capture tables you built during the audit's execution step.
The off-site citation footprint that determines whether the audit's fixes work
Nearly every signal covered so far points back to the same conclusion: AI systems form their opinion of a brand almost entirely from what other people and other publications say about it, not from what the brand says about itself. Wellows' 11-million-citation analysis found that the large majority of brand mentions in AI answers trace to third-party pages, concentrated in listicles, comparison pages, and review roundups, not to owned domains. Branded mentions on other sites beat backlinks roughly three to one in correlation strength with AI visibility. Community platforms carry a large share of citations on their own. And a structural citation bias, where a brand's competitors consistently appear in an AI system's preferred sources and the brand itself does not, cannot be corrected through changes to the brand's own website, no matter how well structured that website becomes.
That is the fix most teams underinvest in, because it is the one that cannot be completed through a content calendar or a developer sprint alone. Earning a mention in a community thread, a comparison listicle, or an earned media placement takes sustained digital PR and a genuine, visible presence in the communities an AI system already trusts, which is a slower and less controllable process than editing a homepage. Layer 1 and Layer 2 fixes establish the entity and correct the narrative, and Layer 3 work is what then gets cited once the model has something accurate to point to, so the audit framework places this layer last for a reason. Skipping straight to earned citations without first fixing the entity and narrative underneath them wastes the investment: an AI system that cannot resolve who a brand is has no foundation on which to credit a mention when it finds one.
Sources
- Brand Visibility in LLMs: How to Audit & Improve It (2026)
- AI Brand Perception Audit: How AI Describes You vs Competitors
- Audit Your Brand Visibility on LLMs (Manual + Tools)
- AI Visibility Audit: 15-Prompt LLM Audit Framework (2026)
- "If I Had to Buy Just ONE: Galaxy S26 Ultra": Auditing AI-Generated Product Recommendations