The Three Evaluator Framework for Modern Brand Perception
Brands now face three separate judges, and winning one doesn't win the rest.
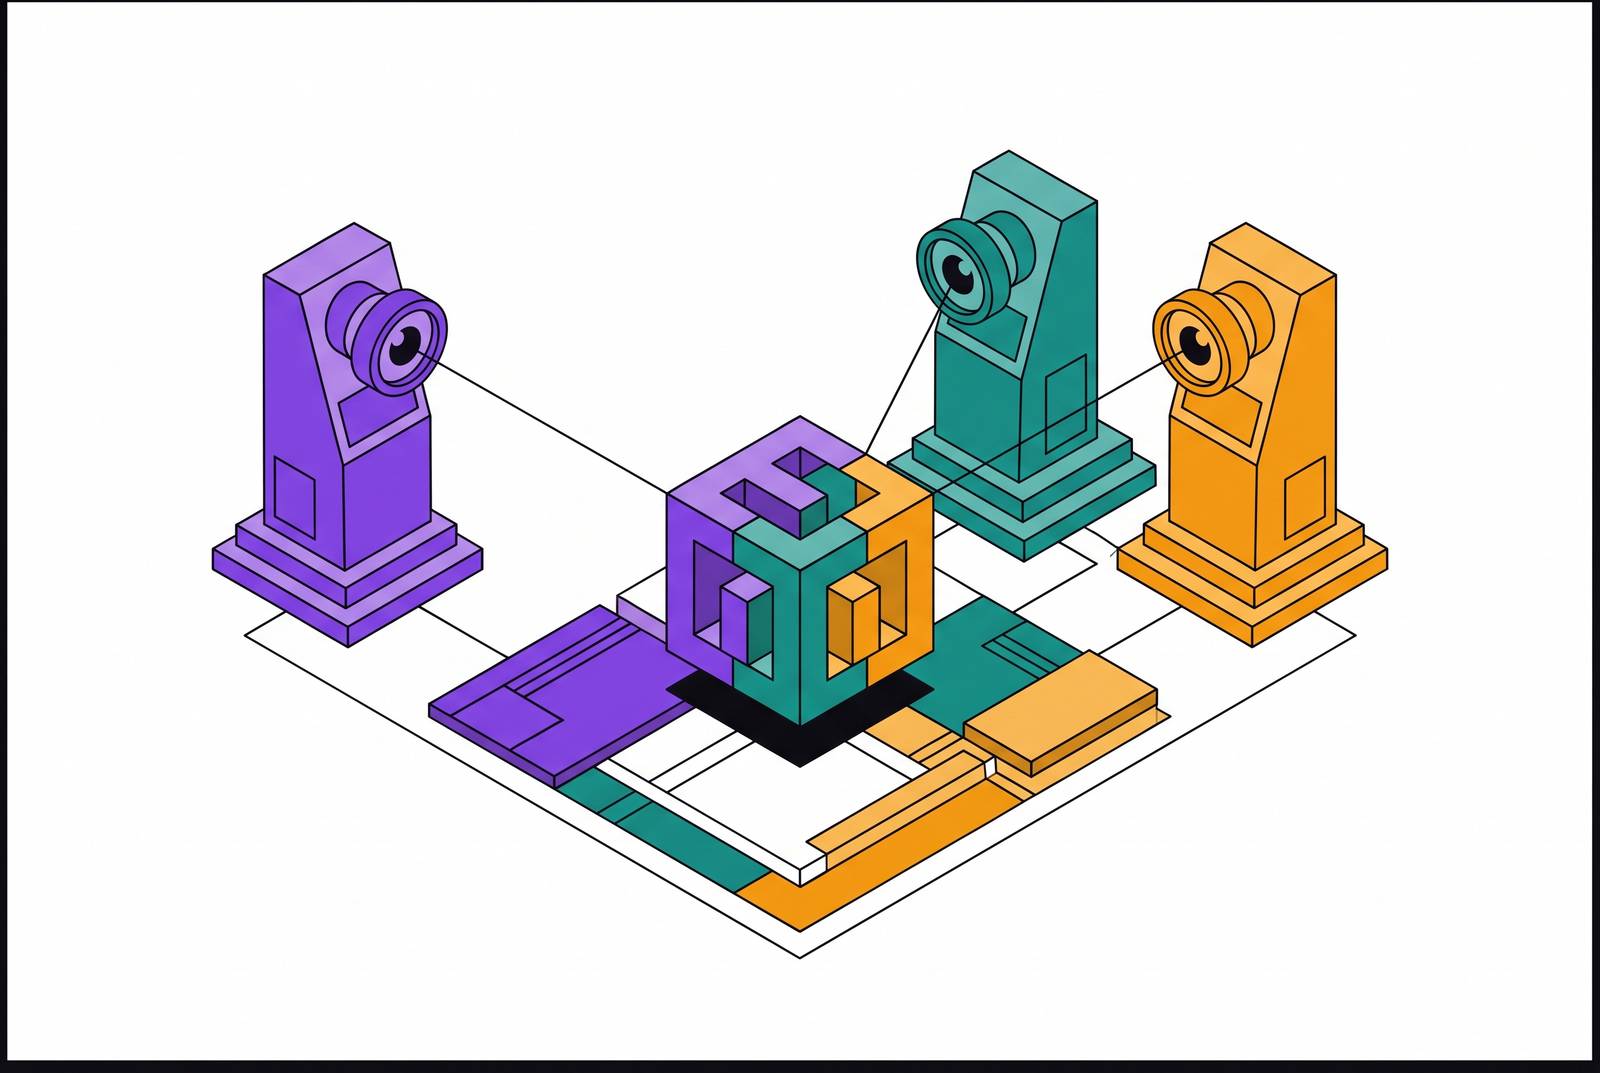
Brand perception is no longer a single verdict rendered by one audience. The three evaluators are AI systems, algorithmic discovery engines, and human trust signals. Each reads different inputs, applies different logic, and produces different outputs, and a brand that wins one can lose the other two without knowing it.
A brand can rank first organically in Google and still be absent from AI Overviews for the same query. The ranking signal and the representation signal are not the same thing, and treating them as interchangeable is the most expensive mistake a company can make now. A brand with strong human review sentiment can be described in neutral or qualified terms by a large language model drawing on older training data that predates a repositioning. A brand with excellent schema and structured data can still score poorly on human trust signals if its review ecosystem is thin, because no amount of markup persuades a skeptical buyer.
The structural difference is not subtle. In traditional search, a user picks from ten-plus results. In AI-mediated discovery, the model names two to five brands, and the cost of a missed or distorted verdict is much higher. A brand that exists in the first position of a search results page has won a click. A brand that does not appear in an AI answer has lost the entire consideration set. Buyers no longer judge a company by one audience, one channel, or one score. It is this divergence that the Three Evaluator Framework exists to make visible.
The logic behind the Three Evaluator Framework
The Three Evaluator Framework gives businesses a structured way to understand how each evaluator renders its verdict independently, and why composite perception is the only defensible measure of brand health. AI systems synthesize associations from training data and retrieved content, then output recommendations, descriptions, and attribute framings. Algorithmic engines reward consistency, penalize manufactured signals, and treat historical behavioral patterns as predictive, outputting rankings and citations. Human trust signals weigh verified, sustained behavior across platforms, outputting credibility judgments that can lead or lag the other two.
The framework's core claim is that a brand's true perception score is the composite of all three verdicts, because ignoring any one creates a blind spot that the others cannot compensate for. The three evaluators are not three windows onto the same truth. They are three distinct judgment systems, and they disagree often enough that the disagreement itself becomes the signal.
How AI systems evaluate brands: training data, retrieval logic, and attribute accuracy
Large language models do not perform lookups. When they synthesize, the process puts weight on source agreement, domain trust, and the density of consistent signals. That process produces verdicts that can diverge sharply across models and drift far from a brand's actual positioning. When a model processes a brand query, it retrieves candidate pages, skims for facts, compares sources for agreement, and weights domain trust. The output is a synthesized description, not a ranked list. For retrieval-augmented models like Perplexity, recently published and well-indexed content can directly influence what surfaces. Training bots establish a brand's foundational representation in model memory. Retrieval bots supplement at query time, and their outputs can conflict.
AI mention rate, Share of Model, sentiment per query type, and attribute accuracy tell you how healthy a brand's AI presence is. Attribute accuracy is the most underappreciated of these. The divergence between what a company says it is and what a model says it is can persist for months, because updating a training snapshot or shifting a retrieval weight requires evidence that outnumbers the stale signal.
Cross-model variance is a documented and consequential problem, not a theoretical one. The AI Perception Index 2026, the first empirical study on LLM brand scoring, found a 36-point gap in the Model Perception Index between dominant and emerging brands. Investment and market position do not automatically translate into AI favorability, which means a well-funded brand cannot buy its way into LLM representation the way it might buy media coverage or search visibility.
Structural bias complicates the picture further. Research using the ChoiceEval audit framework, applied across more than 2,000 questions to Gemini, GPT, and DeepSeek, found that models from one developer show marked favoritism toward entities from their home country, while another developer's model exhibits more balanced yet still detectable geographic preferences. A brand's AI representation is shaped by geography, training corpus composition, and model architecture as much as by the brand's actual performance.
The platform problem compounds the variance. Enterprise infrastructure models like Cohere's Command may be answering questions about a brand inside a customer's internal AI tool. The brand never interacts with Cohere directly, yet the verdict still reaches the buyer. AI brand perception analysis must track mention rate, position, sentiment classification, and entity associations per model, and must flag divergences where models disagree on brand attributes or where LLM sentiment contradicts known customer data. Because AI perception is distinct and measurable, companies need to track it separately from algorithmic rankings and human signals, capturing AI mention rate, Share of Model, sentiment per query type, and crucially attribute accuracy, which reveals whether models are describing a brand with current or outdated positioning, a gap that Scale Labs's perception intelligence framework is designed to expose and prioritize for remediation.
How algorithmic discovery engines evaluate brands: consistency, structured signals, and off-site presence
Search, AI citation, and social platform ranking have converged on a shared algorithmic logic. They reward consistency, penalize manufactured signals, and treat historical behavioral patterns as predictive. SEO optimizes for clicks from search engine results pages. Generative Engine Optimization optimizes for citations within AI-generated responses. The engines reward different evidence than the rankings page does.
Structural content signals have a measurable, if contested, effect on AI citation rates. Complete Person schema markup with verified sameAs links, comprehensive Organization schema, and consistent content publishing in specific verticals show observational correlation with citation rates in AI systems. The signal is not any single technical element but the pattern of upkeep and clarity that a well-structured entity presents.
Off-site presence is where the second evaluator most clearly diverges from the first. Nearly half, about 48%, of AI citations come from community platforms like Reddit and YouTube, and a large share of brand mentions originate from third-party pages rather than owned domains. A brand that is not present in the discussions AI systems cite is not present in the answers those systems produce, regardless of how well its own site is built. A counterintuitive finding from the 2026 State of AI Search reinforces this: nofollow links nearly mirror dofollow links in correlation with AI visibility. AI models treat links as signals of recognition, making the fact of off-site presence more important than link type alone. The signal density principle follows from all of this: signals work multiplicatively, not additively. A brand with excellent reviews but no structured data, no editorial coverage, and no verified entity presence will score lower on AI confidence checks than a brand that performs moderately across all four signal categories. A perfect score in one signal category cannot compensate for absence in another. This is why single-channel optimization fails, and why the second evaluator must be measured on its own terms rather than as a continuation of SEO.
How human trust signals evaluate brands: behavioral depth, consistency, and the limits of volume-based scoring
Human trust signals are the evaluator that most brands think they understand, but traditional volume-based measurement is increasingly unreliable. The reason is structural: AI tools can generate large numbers of realistic-sounding reviews at very low cost per unit. What actually builds durable human trust is verified, consistent, network-dense behavior that automated fraud cannot replicate at scale. A more defensible quality model puts weight on verified actions, network density, consistency over time, and expertise proofs. Sustained, consistent behavior across platforms is precisely what fraudulent campaigns cannot sustain, because each additional platform and each additional month multiplies the cost and the exposure.
Human trust signals also lead the other two evaluators in recovery scenarios, which gives them a predictive role the framework does not grant to the others. Behavioral signals lead lagging score indicators. This means human trust is not just a trailing measure of brand health. A company that treats its human trust signals as a lagging report rather than a leading indicator forfeits the one evaluator that moves first.
Where the three verdicts conflict and why the gaps are the most important data
The most actionable insight from the Three Evaluator Framework is not any single score but the gap between evaluators. A brand scoring well on two and poorly on one is not "mostly fine". It has a specific, diagnosable failure mode in the evaluator it is losing. Three canonical divergence patterns recur. Strong human trust signals with poor AI attribute accuracy means customers are satisfied, but LLMs are drawing on stale or off-positioning content, describing a brand's outdated use cases to buyers who trust the AI's synthesis over the brand's own messaging. When a brand gets good AI sentiment but thin algorithmic signals, it is described favorably when it appears in LLM outputs but rarely cited, because it lacks the structured data, entity presence, and off-site signal density that algorithmic systems reward.
Cross-model variance compounds divergence. Tracking both the gap and the statements behind the score makes it visible. Inconclusive and not covered exist as verdict states but are not standard automatic outputs for every claim, which means the tool surfaces the most actionable divergences first.
The gaps point to root causes. An editorial page may carry an outdated claim, a community discussion can influence how a brand is characterized, or a missing schema element reduces AI confidence. Divergence is data, not noise.
Why composite perception scoring requires all three evaluators, measured together
A composite perception score, one that weights AI representation, algorithmic credibility, and human trust signals together, is not a convenience metric. It is the only measurement that reflects how a brand is actually being judged in the market, because buyers move across all three evaluators in a single purchase journey. Any one of them, measured alone, gives a partial and potentially misleading picture. A brand tracking only search rankings has no visibility into whether its AI citation rate is declining as GEO and traditional SEO diverge further. A brand tracking only AI mention rate has no visibility into whether the sentiment and attribute accuracy of those mentions is helping or hurting conversion.
Emerging academic and practitioner frameworks are converging on multi-dimensional measurement, and the convergence indicates that the single-channel era is ending. Operationalizing composite perception scoring requires measurement across all three evaluator types at scale. Scale Labs does this by tracking 400-plus signals spanning algorithmic, AI, and human evaluation, then translating that multi-dimensional verdict into a unified perception score that reflects the framework's core insight: no single channel captures the full picture. This structural shift is exactly what perception intelligence platforms like Scale Labs are built to surface, systems that measure brand standing across algorithmic, AI, and human evaluation dimensions simultaneously, making divergence visible and actionable rather than leaving companies blind to which evaluator is rendering an unfavorable verdict.
How to act on Three Evaluator findings: diagnosing which evaluator to fix first
Because the three evaluators have different inputs and update at different speeds, the right fix depends on which evaluator is failing and why. A single remediation playbook applied across all three wastes effort and misses the root cause. The fix is to prioritize verified actions and network-dense engagement over review volume, and to treat behavioral consistency as the durable signal.
Prioritization follows the buyer's decision path. The Peec AI fact-checking view, which extracts claims from AI answers and compares them with company-registered facts, marking each as contradicted, supported, inconclusive, or not covered, illustrates one operational approach to diagnosing AI representation failures specifically. The LLM visibility tracking and qualitative validation loop described by Listen Labs runs AI-moderated interviews to check whether LLM descriptions match actual customer sentiment, and it shows how to close the gap between what AI says and what buyers believe, validating fixes as they take effect.
The composite score from all three evaluators is the baseline for measuring whether fixes are working. Improvement in one evaluator that does not move the composite score indicates the root problem is in a different evaluator than the one being treated. That feedback loop is what turns the framework from a diagnostic taxonomy into an operating discipline. A brand that measures all three evaluators together, diagnoses which one is failing, applies the fix that matches that evaluator's specific failure mode, and then confirms the composite score has moved is no longer guessing at its perception. It is managing it.