Turning Raw AI Perception Data Into a Normalized Brand Score With Competitive Standing
How AI systems independently score your brand against competitors—and why that matters.
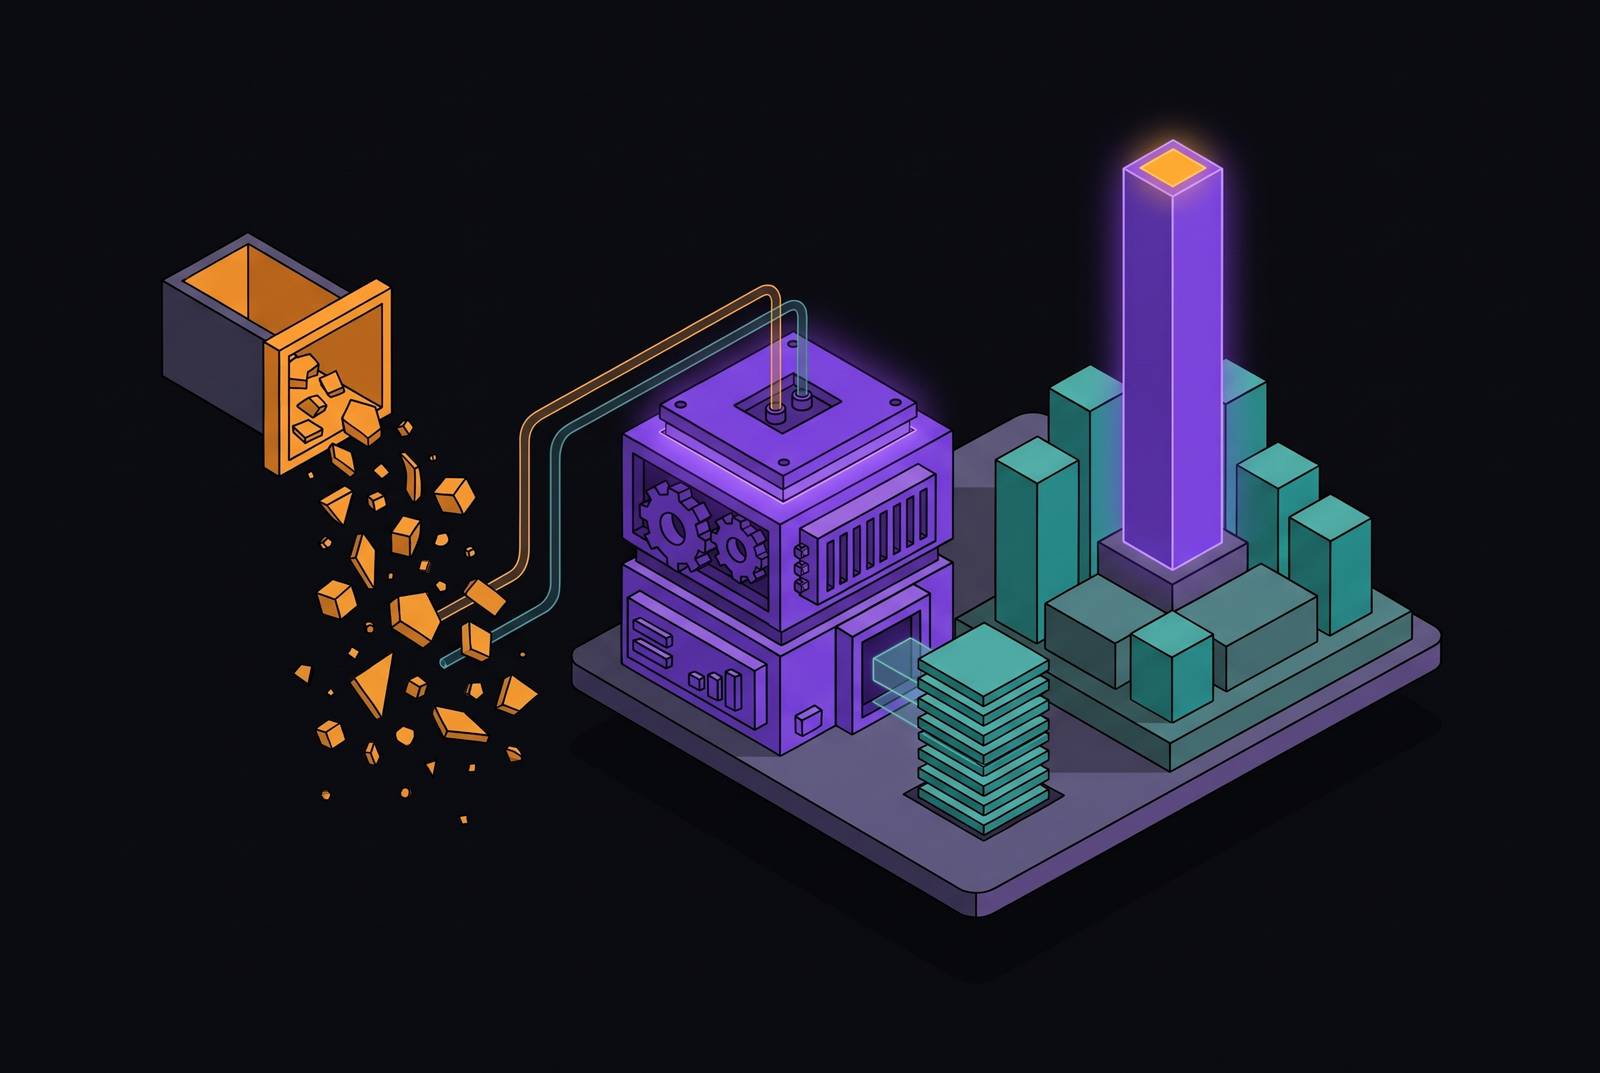
AI brand perception audit and scoring turns what chatbots say about a brand into a comparable measure of presence, sentiment, and accuracy. A meaningful score requires standardized prompts, observations across models, explicit normalization, and justified weights. This article explains that pipeline and why its real payoff is competitive standing, which shows not just how a brand performs, but which gaps deserve attention first.
Why AI models form independent opinions about brands — and why those opinions can diverge sharply from human perception
AI models do more than retrieve a company’s description of itself. They synthesize associations from training data and real-time retrieval into confident conclusions, often ranking brands against alternatives. Those judgments can shape what buyers choose even when they differ from how the brand wants to be seen or how its customers see it. The brand supplies its pitch, but it does not chair the jury.
WPP’s Aura research at WRC 2026 found that a brand’s website accounts for only a small fraction of the material AI models draw on. Reviews, editorial, forums, and community content make up almost all the rest. That leaves the copy a brand knows best with the least influence over the resulting synthesis. The gap goes beyond who controls the wording. It changes which evidence defines the brand.
The same research applied the BAV brand equity framework, measuring differentiation, relevance, esteem, and knowledge, across six AI models and a large set of brands. The results diverged sharply from consumer survey data for those brands. Models bring no emotional loyalty to the task, assess price-to-value through feature comparisons, and treat unverified marketing claims as noise. The beloved logo gets no sentimental allowance.
The AI Perception Index 2026 also found substantial perception drift for the same brand across AI systems. So the divergence is not simply between humans and machines. Any account of AI perception must track how models differ, since one chatbot’s answer cannot speak for them all.
How do you find out what AI chatbots are saying about your brand right now — and why are raw answers hard to compare?
The raw material is a collection of responses to relevant queries, with separate observations for different models and prompts. It contains four core signal types, namely mentions, sentiment, accuracy, and competitive context. Mentions show whether and how often a brand surfaces. Sentiment captures the tone of that appearance, while accuracy concerns whether the claims are correct and current. Competitive context shows how the response compares the brand with the alternatives it names.
“Known for excellent service” expresses sentiment directly, while “users have reported concerns” qualifies the recommendation. A passing mention also differs from a prominent recommendation, even when both contain the same brand name. Counting names alone flattens those distinctions.
The responses also blend two different information sources. Training-data associations build up from past web content, change slowly, and may be out of date. Retrieval-augmented generation, or RAG, supplements those associations with real-time web pulls in systems such as Perplexity. Retrieval updates faster but can be influenced by a single high-authority negative piece.
Prompt framing adds another source of variation. A category recommendation, price comparison, and enterprise use-case query can produce materially different treatment of the same brand. Responses from GPT-4o and Claude Sonnet are likewise separate observations. Normalization is the transformation that makes its different forms comparable without pretending they were identical to begin with.
The signals that carry weight in LLM evaluation — and how their influence is distributed unevenly
Source authority, structure, and third-party corroboration influence AI representation unevenly. A well-linked industry report can outweigh many mentions in thin content, so volume is not a reliable substitute for influence. A brand can be mentioned often without accumulating equally strong evidence.
Structured content helps AI systems retrieve and verify claims. FAQ schema, JSON-LD markup, and structured data tables give those claims a form that is easier to assess than unverified marketing copy. When entity signals are absent or inconsistent, models can fall back on cautious framing and reduced share of voice. Structure makes a claim easier to identify and evaluate.
E-E-A-T signals serve as search ranking factors and also act as inclusion criteria for AI responses. Experience, expertise, authoritativeness, and trustworthiness influence whether a source is treated as citable. In RAG-dependent systems, recency adds another influence because fresh, well-indexed content is more likely to enter the retrieved material. Authority and freshness are different things, even when a source has both.
Consistency across sources supplies another kind of evidence. The same entity name, attributes, and facts appearing coherently across independent sources provide corroboration. For measurement, these distinctions justify separating source quality, factual consistency, and visibility. A loud signal and a dependable signal are not necessarily the same thing.
How a normalization pipeline converts inconsistent LLM outputs into comparable scores
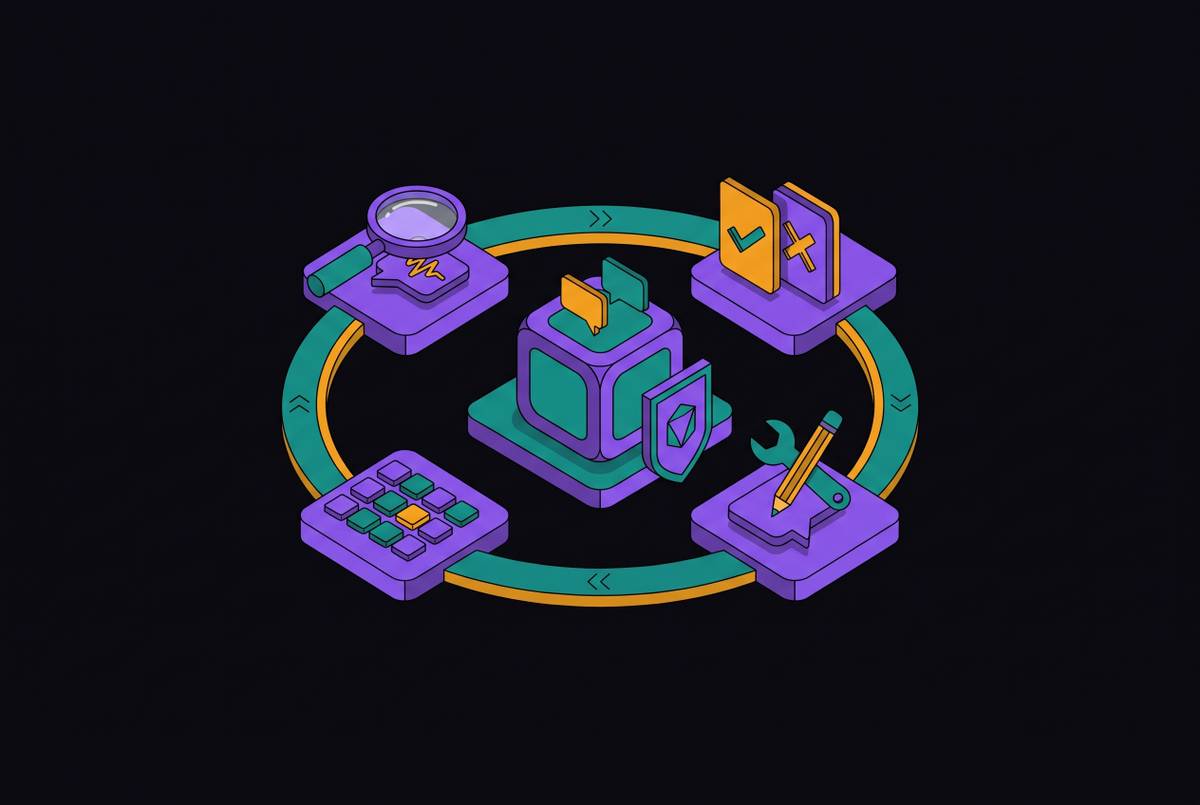
A defensible pipeline has distinct stages, including prompt design, raw output collection, dimension scoring, normalization, and weighting. Each stage solves a different problem. Prompt design defines the questions being tested, collection captures the responses, and dimension scoring interprets them. Normalization makes those readings comparable before weighting combines them. Skipping a stage leaves the final number dependent on differences the method has not accounted for.
Prompt design starts with standardized, non-branded questions that reflect how people search in the category when they have a strong intent to buy. Category, use-case, and comparison questions reveal whether a brand appears organically in responses rather than merely appearing because the prompt requested it. The query set also needs to remain fixed for comparisons over time. Otherwise, a change in results may reflect a change in the test. Moving the goalposts is easier than improving the score.
Collection then spans multiple models and runs. The cross-model drift found in the research shows why measuring one model leaves out part of the picture of AI perception. Multiple runs also provide the observations needed to assess stability. Answers from each model stay separate at this stage. Combining them too early would hide the variation the pipeline is meant to explain.
Dimension scoring translates those answers into defined criteria before aggregation. Presence and mention quality capture appearance, position, and framing, while sentiment favorability distinguishes positive, neutral, and qualified or negative treatment. Accuracy checks whether the answers get brand attributes right, while competitive position tracks how they treat the brand compared with other options. Source and citation quality assess the evidence behind the answer. Cross-model consistency captures how stable that representation is across systems.
Normalization places the resulting dimension scores on a common scale. Without it, the range of the measurement instrument can distort a composite’s representation of the brand’s standing. The method must make explicit how readings from different models and prompt types become comparable before they contribute to a shared result.
Weighting then determines each dimension’s contribution to the composite. The LLM Visibility Index methodology illustrates one approach with a 0–100 score built from presence and mention quality, position in the answer, query coverage, and share of voice. Share of voice receives the highest individual weight. That is a published architecture. Its choices illustrate why a score needs a stated purpose and visible weighting logic.
Handraise’s published scoring architecture has more parts. It includes narrative presence, prominence, brand-centric favorability, message pull-through, accuracy, competitive position, citation quality, source authority, cross-model consistency, cross-run stability, retrieval resilience, and earned-media evidence strength. Broader coverage still requires justified weights, grounded in measured influence on recommendation outcomes. Neither complexity nor a neat number establishes usefulness by itself.
Establishing competitive standing — how to benchmark a normalized score against peer brands
Peer selection determines what the comparison means. AI models recommend options within a buying context, so a brand’s position against relevant alternatives is more useful than an isolated result. The visibility methodology states that it uses category-relative normalization, comparing banks with other banks and mobile phone brands within their own category. A common scale alone is not enough. The comparison group must also make sense.
The perception index found a 36-point gap between dominant and emerging brands on its Master Perception Index. Funding level did not reliably predict performance, with highly funded brands scoring nearly identically to bootstrapped firms. That finding suggests content and signal quality shape standing. A large budget is not a reserved seat in the answer.
Benchmarking needs to preserve at least four separate dimensions before combining them. Favorability shows which brand receives the most positive treatment, while competitive position shows which is recommended first or most often against alternatives. Accuracy reveals whose attributes are represented most reliably. Completeness asks whether the response surfaces the full value proposition or reduces it to a generic description. A flattering answer can still omit what makes a brand distinctive.
Share of voice within AI responses adds a direct competitive KPI. It measures how often a brand appears relative to named competitors when models compare options, rather than relying on share-of-voice measures built for traditional search. A dimension-level benchmark then makes the shortfall specific. A competitor’s advantage in citation quality, for example, describes a different problem from an advantage in factual accuracy.
Evident’s AI Index for Banks shows how to build a structured peer comparison by assessing entities across 70+ individual indicators and four pillars of analysis: Talent, Development, Leadership, and Transparency. They are not the AI perception dimensions described here. The distinction is important when choosing measurement tools. A multi-indicator bank benchmark demonstrates a comparative structure, but its indicator count alone does not establish that it measures how chatbots represent brands.
For an AI perception benchmark, the relevant infrastructure must connect the earlier stages to the peer comparison. Standardized prompts, multi-model observations, dimension scores, and explicit normalization make the resulting rank interpretable. The dimension breakdown then exposes vulnerability.
What the competitive score reveals that dimension scores alone cannot — and how to act on the gap
A dimension score describes performance on one axis. Competitive standing shows whether that performance is a strength or a disadvantage against the brands buyers encounter in the same answers. The benchmark also reveals which dimension gaps create the largest distance from the leading competitor. Not every deficit deserves equal effort. The useful output is a prioritized repair map.
The practical response depends on the kind of gap. An accuracy deficit points toward entity-data inconsistency, making structured markup, schema, and factual claim density in indexed content relevant levers. A citation-quality deficit points toward insufficient presence in high-authority third-party sources, where earned media, peer-reviewed mentions, and industry publication placements are the corresponding levers. These are different repairs. More favorable wording does not fix a wrong attribute.
A cross-model consistency gap calls for corroboration of core attributes across multiple independent sources. A competitive share-of-voice gap instead points toward prompt coverage and content breadth across category-level query types. Without that connection, optimization can become a busy exercise in fixing whichever issue is easiest to name.
This is why brand perception cannot be reduced to sentiment. Positive tone does not establish accurate attributes, complete positioning, or competitive differentiation. The themes and attribute associations embedded in online content also shape how brands differ in AI responses. Dimension-level analysis preserves those distinctions.
The measurement also needs to continue after the first audit. RAG-dependent systems retrieve in near real-time, while later training runs incorporate more recent web content over time. An unrefreshed score therefore describes a past state. This ongoing discipline is perception intelligence, which connects brand management, NLP, and competitive intelligence rather than substituting for SEO, social monitoring, or traditional brand tracking. Businesses seeking to close competitive gaps need that measurement in place before optimization, so the work begins with evidence of what to fix first.