How to Score Your B2B Brand's AI Credibility Across the Signals That Actually Move the Needle
A four-signal scorecard shows where AI trusts your brand.
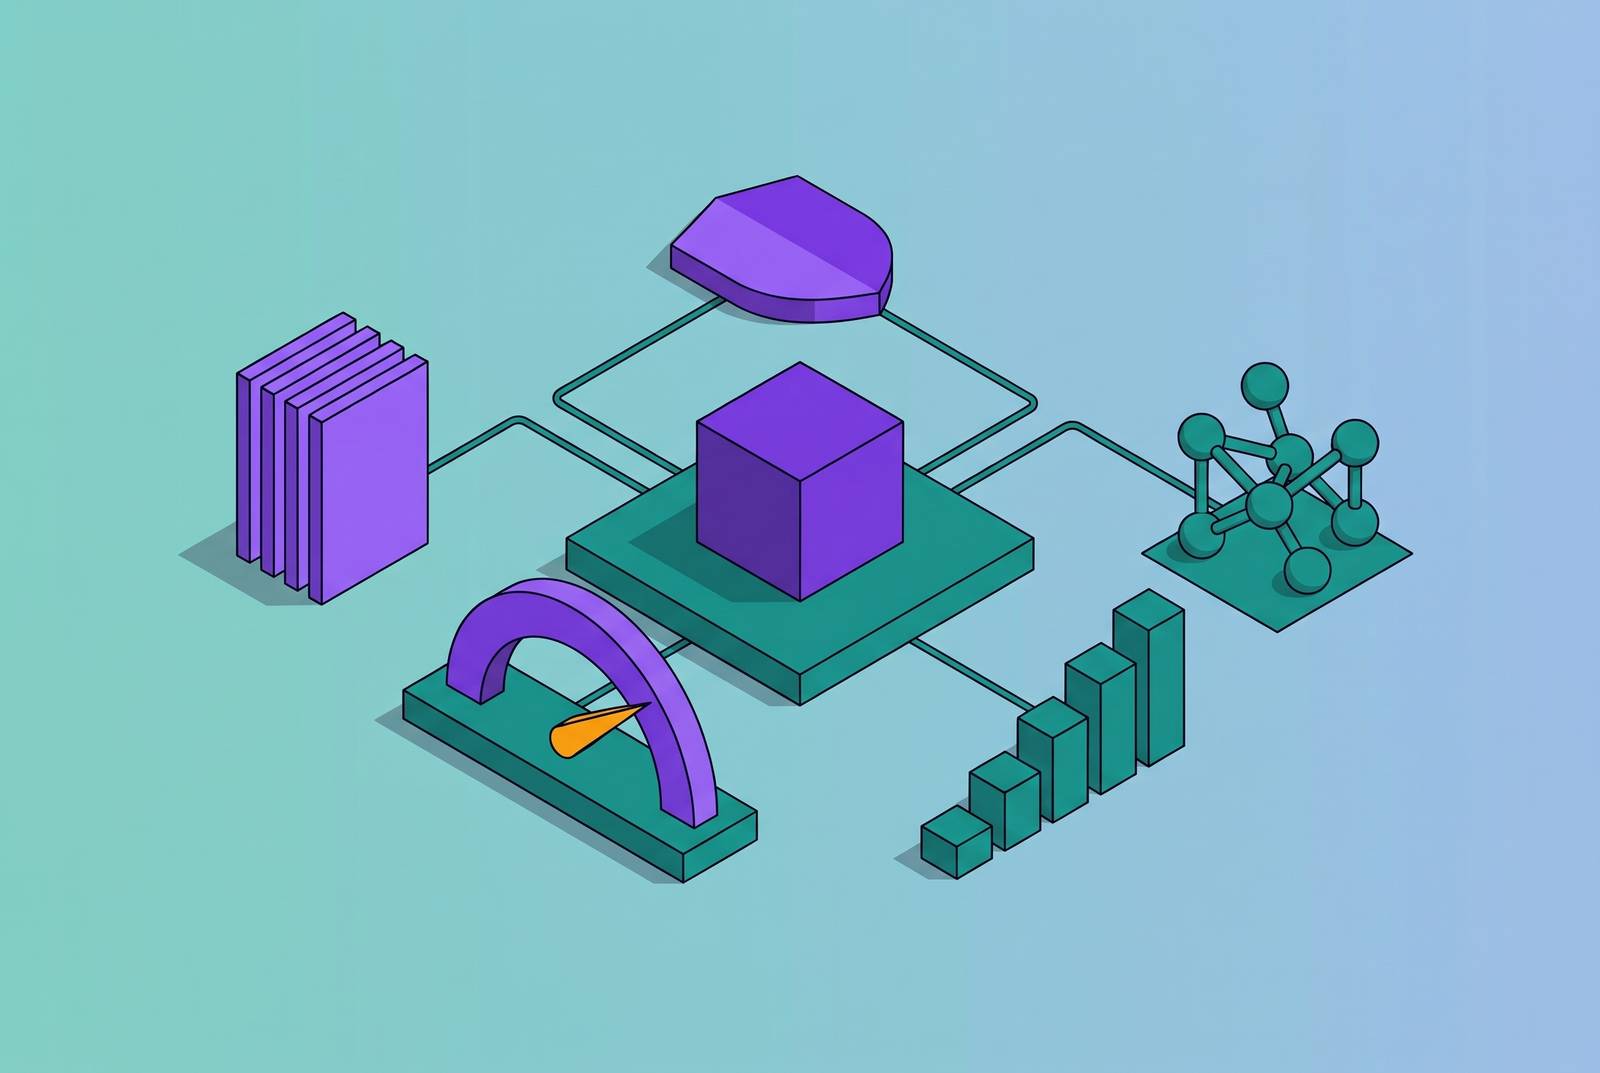
LLMs evaluate B2B vendor credibility through four signals, which are entity consistency, third-party corroboration, demonstrated expertise, and verifiable claims. These signals help an AI assistant understand what a company does, connect it with independent evidence, and explain why it fits a buyer’s needs. Scoring them gives marketers a repeatable way to improve the evidence behind recommendations, rather than treating online presence as proof of credibility.
Why AI recommendation visibility is structurally different from search ranking visibility
The B2B buying funnel now routes through AI before it reaches a vendor. During that pre-contact research, buyers can ask an assistant to compare suppliers without visiting the pages a marketing team worked hard to rank. A brand can perform well on Google yet be absent from the answer that shapes the shortlist.
That distinction changes who enters a sales conversation already preferred. A vendor that appears repeatedly in AI-mediated research can become the buyer’s favorite before another vendor even knows there is a deal. The website is no longer the whole audition. AI systems synthesize evidence about a company across sources, rather than simply presenting a ranked page for the buyer to inspect. As a result, the marketing work must extend beyond making pages discoverable to making the business independently understandable and credible.
How do LLMs evaluate B2B vendor credibility?
AI credibility assessment is a pattern-recognition process. Xeo Marketing’s credibility framework looks at whether it is clear what a company does, whether independent sources describe it the same way, whether its expertise is out in public, and whether its products can be explained with confidence. The common thread is uncertainty. A system has a stronger basis for recommending a vendor when the available evidence supports a coherent description.
Consider Vendor A and Vendor B. Vendor A describes itself in different ways on its website, in company profiles, and in published content, so it is unclear which category it belongs in. Vendor B uses a consistent description of what it offers and whom it serves. Even if B is smaller, its clarity can make it easier for an assistant to explain and recommend. Size does not resolve a muddled identity.
Clarity alone, however, does not establish expertise. When what a company knows stays in sales decks, client projects, and talks within the company, an answer engine has little public evidence to use. Nor does a confident claim on a homepage establish that the claim is true. Those distinctions turn the broad idea of credibility into separate, auditable signals.
Why most B2B teams discover their AI credibility gap only during the audit
A marketing dashboard shows how much content a team publishes and how well it does in search, but it is easier to miss a lack of independent corroboration. A team can therefore think that publishing a lot means it has strong AI credibility. Owned content and paid media may make a company better known without giving an answer engine the outside evidence it needs. The dashboard can look healthy while the shortlist disagrees.
Skyword’s audit scenario makes the gap concrete. Unbranded queries returned competitors, while branded queries surfaced outdated product information. Beyond more content, the company needed to understand both where it was absent and where its existing description was wrong. Even a technically sophisticated team can miss that distinction until it looks directly at AI answers.
For a marketing team, the practical first step is an audit using existing tools, including ChatGPT, Perplexity, and Gemini. Unbranded questions show whether the company comes up in discussions of its category, while branded questions show where descriptions are wrong or claims are out of date. The useful output is a signal gap map. It should distinguish weak evidence from missing evidence and show which of the four categories deserves investment first.
Signal 1 — Entity consistency: whether AI can form a stable, unambiguous picture of your brand
Entity consistency establishes whether an AI system can reliably identify the company behind the evidence it finds. If the homepage, About page, case studies, and LinkedIn profile describe different businesses, strong content may not resolve the confusion. The system needs a stable account of what the company does, whom it serves, and where it fits. A brand should not require a detective.
To score this signal, check that the name, address, and phone are correct in major directories and on major platforms. Then check schema coverage for each page type and compare how the company names its category in its main public descriptions. A wrong address is an accuracy problem, missing markup is a coverage problem, and conflicting category descriptions are a coherence problem.
Structured data gives this audit a technical layer, but the underlying question remains simple. Does the public record describe one recognizable business? Schema coverage should be checked across the pages that need it, even if one page has schema that is done well. Fixing these gaps makes the company more legible to AI systems, but legibility is only the prerequisite. Outside support for that picture remains to be checked.
Signal 2 — Third-party corroboration: the signal type AI weights most heavily
Editorial coverage, verified reviews, analyst mentions, and community citations give an answer engine evidence from people outside the company. When those sources describe the company the same way, there is less doubt. When they conflict, or only the brand is speaking, the case for recommendation weakens. Self-praise is still self-praise in excellent typography.
The key distinction is editorial independence. An earned feature in a respected trade publication represents a judgment that press release distribution or sponsored content does not replicate. Publishing more on the company blog cannot manufacture that independence. Exact model weights are not public, so “most heavily” should guide investment in outside evidence.
To score corroboration, count editorial mentions in named industry publications over the past 12 months, verified reviews on independent platforms, and analyst or community citations in category discussions. Keep those evidence types distinct. Reviews deserve continued attention after launch. Together, these sources help establish that a company is real and trusted. They do not, by themselves, establish that it is the best source of knowledge about a particular problem.
Signal 3 — Demonstrated expertise: making visible the knowledge that is currently trapped inside the organization
Demonstrated expertise turns private knowledge into public, attributable evidence. A company may have deep experience solving a buyer’s problem, yet publish only broad explanations that any competitor could produce. AI systems cannot assess the expertise that stays inside project discussions.
Specificity helps close that gap. Salesforce’s role-specific, industry-specific content includes lead routing for financial services sales teams, patient engagement for healthcare admins, and implementation playbooks for retail marketers. These subjects show how knowledge helps a given user with a given task, going beyond a broad explanation of CRM. Original proprietary research provides a different kind of distinction because a finding can be traced to its source. Consistently named frameworks can likewise connect a concept with the brand that developed it.
To score expertise, assess named authorship, verifiable credentials, and machine-readable Person schema, then examine how closely content addresses specific buyer roles and use cases. Identify proprietary research and named frameworks separately from general topic coverage. The irony is that using AI to produce interchangeable content can make a brand harder to distinguish in AI answers. Human experts supply the insight and judgment. AI can help with execution. Public expertise gives the system something worth citing, but the claims behind it still need to hold up when checked.
Signal 4 — Verifiable claims: what AI checks when it tries to confirm what a brand asserts
Verifiable claims give an answer engine evidence it can check against named case studies, pricing guidance, independent reviews, and specific results. A claim without that support may be ignored or presented with uncertainty. This ties the previous signals together. A clear company identity, outside recognition, and visible expertise need to point toward assertions that can actually be checked.
When the company’s own claims lack retrievable support, inaccurate information from other sources can shape the answer instead. That is why branded audit queries are useful. Outdated product descriptions or contradictory statements reveal where the public evidence has drifted from what the business offers. The response is accurate, authoritative content.
To score verifiability, assess the percentage of case studies that name clients and include specific, measurable outcomes. Check whether any pricing guidance is public, whether FAQ-format content has FAQPage schema, and whether AI answers repeat claims that contradict the actual offering. These are practical evidence checks. They also distinguish a missing proof point from a circulating falsehood, which helps the team decide what to address first.
How to build a scoring lens across the four signal categories
A useful scoring lens records each category’s current state, the gap in its evidence, and the effort required to close that gap. No framework can guarantee a citation or a particular recommendation. AI systems do not disclose their full weighting, and retrieval continues to change.
For entity consistency, use NAP checks to score how accurate and complete the record is, check schema coverage by page type, and check that category language stays the same. For third-party corroboration, score evidence from outside the company by checking editorial mentions over the past 12 months, verified reviews, and analyst or community citations. For demonstrated expertise, score attributable depth through credentialed authorship, Person schema, buyer-specific content, proprietary research, and named frameworks. For verifiable claims, score retrievable proof through named case studies with measurable outcomes, pricing guidance, FAQ schema, and the absence of circulating misinformation. Keeping the dimensions separate prevents strength in one area from hiding a serious gap in another.
The weighting should help teams decide what to do while making no claim to match a model’s internal formula. Entity consistency and verifiable claims are foundational and usually fastest to address, with claim verification often providing the highest return on an early fix. Third-party corroboration takes longest to build, so that work should begin immediately regardless of the current score. Demonstrated expertise supplies the differentiation that can make a brand a cited authority.
Combined, these assessments show which investments are practical now and which require sustained work. Quarterly re-audits reveal whether the evidence is improving and whether AI answers have drifted despite no obvious change by the company.
What sustained AI credibility building looks like in practice for B2B marketing teams
Over a 12-month horizon, the work combines ongoing corroboration with quarterly checks. Editorial relationship building, proactive review generation on verified platforms, and analyst engagement need continuity because outside recognition is not an asset a team can summon on launch day. Re-audits across ChatGPT, Perplexity, and Gemini help catch omissions, misinformation, and changes in visibility.
Human experts bring the specific knowledge and credentials, while AI tools can speed up research, help put schema in place, and get content out. People still decide which claims are defensible before publication. They also choose whom to write focused content for and which ties to build with editors. AI can speed the work without becoming the source of the expertise.
For teams without that capacity in-house, an agency combining AI tooling with human strategic judgment is one route. The requirement spans both technical work, including structured data and retrieval optimization, and brand judgment about what knowledge to surface. Neither half substitutes for the other. A technically legible brand with nothing distinctive to say remains easy to overlook.
The advantage compounds when clear descriptions, credible outside references, and attributable expertise reinforce one another. Recommendation citations can strengthen external corroboration, which can support future citations. That loop takes time to build, giving brands that start now an advantage over those waiting for AI to feel settled. More content is a production target. Better-supported credibility is an asset.